Microsoft's Tomasz Janczuk released iisnode "The iisnode project provides a native IIS 7.x module that allows hosting of node.js applications in IIS.
Scott Hanselman posted a detailed walkthrough of how to get started with iisnode
diff --git a/doc/blog/Uncategorized/the-videos-from-node-meetup.md b/doc/blog/Uncategorized/the-videos-from-node-meetup.md
deleted file mode 100644
index 7ca7ac758ce..00000000000
--- a/doc/blog/Uncategorized/the-videos-from-node-meetup.md
+++ /dev/null
@@ -1,10 +0,0 @@
-title: The Videos from the Meetup
-author: ryandahl
-date: Fri Aug 12 2011 00:14:34 GMT-0700 (PDT)
-status: publish
-category: Uncategorized
-slug: the-videos-from-node-meetup
-
-Uber, Voxer, and Joyent described how they use Node in production
-
-http://www.joyent.com/blog/node-js-meetup-distributed-web-architectures/
diff --git a/doc/blog/Uncategorized/tj-fontaine-new-node-lead.md b/doc/blog/Uncategorized/tj-fontaine-new-node-lead.md
deleted file mode 100644
index 88c80bec69e..00000000000
--- a/doc/blog/Uncategorized/tj-fontaine-new-node-lead.md
+++ /dev/null
@@ -1,54 +0,0 @@
-title: The Next Phase of Node.js
-date: Wed Jan 15 09:00:00 PST 2014
-author: Isaac Z. Schlueter
-slug: the-next-phase-of-node-js
-
-Node's growth has continued and accelerated immensely over the last
-few years. More people are developing and sharing more code with Node
-and npm than I would have ever imagined. Countless companies are
-using Node, and npm along with it.
-
-Over the last year, [TJ Fontaine](https://twitter.com/tjfontaine) has become absolutely essential to the
-Node.js project. He's been building releases, managing the test bots,
-[fixing nasty
-bugs](http://www.joyent.com/blog/walmart-node-js-memory-leak) and
-making decisions for the project with constant focus on the needs of
-our users. He was responsible for an update to MDB to [support
-running ::findjsobjects on Linux core
-dumps](http://www.slideshare.net/bcantrill/node-summit2013), and is
-working on a shim layer that will provide a stable C interface for
-Node binary addons. In partnership with Joyent and The Node Firm,
-he's helped to create a path forward for scalable issue triaging.
-He's become the primary point of contact keeping us all driving the
-project forward together.
-
-Anyone who's been close to the core project knows that he's been
-effectively leading the project for a while now, so we're making it
-official. Effective immediately, TJ Fontaine is the Node.js project
-lead. I will remain a Node core committer, and expect to continue to
-contribute to the project in that role. My primary focus, however,
-will be npm.
-
-At this point, npm needs work, and I am eager to deliver what the Node
-community needs from its package manager. I am starting a company,
-npm, Inc., to deliver new products and services related to npm. I'll
-be sharing many more details soon about exactly how this is going to
-work, and what we'll be offering. For now, suffice it to say that
-everything currently free will remain free, and everything currently
-flaky will get less flaky. Pursuing new revenue is how we can keep
-providing the npm registry service in a long-term sustainable way, and
-it has to be done very carefully so that we don't damage what we've
-all built together.
-
-npm is what I'm most passionate about, and I am now in a position to
-give it my full attention. I've done more than I could have hoped to
-accomplish in running Node core, and it's well past time to hand the
-control of the project off to its next gatekeeper.
-
-TJ is exactly the leader who can help us take Node.js to 1.0 and
-beyond. He brings professionalism, rigor, and a continued focus on
-inclusive community values and culture. In the coming days, TJ will
-spell out his plans in greater detail. I look forward to the places
-that Node will go with his guidance.
-
-Please join me in welcoming him to this new role :)
diff --git a/doc/blog/Uncategorized/trademark.md b/doc/blog/Uncategorized/trademark.md
deleted file mode 100644
index 7494915be10..00000000000
--- a/doc/blog/Uncategorized/trademark.md
+++ /dev/null
@@ -1,17 +0,0 @@
-title: Trademark
-author: ryandahl
-date: Fri Apr 29 2011 01:54:18 GMT-0700 (PDT)
-status: publish
-category: Uncategorized
-slug: trademark
-
-One of the things Joyent accepted when we took on the Node project was to provide resources to help the community grow. The Node project is amazing because of the expertise, dedication and hard work of the community. However in all communities there is the possibility of people acting inappropriately. We decided to introduce trademarks on the “Node.js” and the “Node logo” in order to ensure that people or organisations who are not investing in the Node community misrepresent, or create confusion about the role of themselves or their products with Node.
-
-We are big fans of the people who have contributed to Node and we have worked hard to make sure that existing members of the community will be unaffected by this change. For most people they don’t have to do anything they are free to use the Node.js marks in their free open source projects (see guidelines). For others we’ve already granted them licenses to use Node.js marks in their domain names and their businesses. We value all of these contributions to the Node community and hope that we can continue to protect their good names and hard work.
-
-Where does our trademark policy come from? We started by looking at popular open source foundations like the Apache Software Foundation and Linux. By strongly basing our policy on the one used by the Apache Software Foundation we feel that we’ve created a policy which is liberal enough to allow the open source community to easily make use of the mark in the context of free open source software, but secure enough to protect the community’s work from being misrepresented by other organisations.
-
-While we realize that any changes involving lawyers can be intimidating to the community we want to make this transition as smoothly as possible and welcome your questions and feedback on the policy and how we are implementing it.
-
-http://nodejs.org/trademark-policy.pdf
-trademark@joyent.com
diff --git a/doc/blog/Uncategorized/version-0-6.md b/doc/blog/Uncategorized/version-0-6.md
deleted file mode 100644
index 5cde4c61e7e..00000000000
--- a/doc/blog/Uncategorized/version-0-6.md
+++ /dev/null
@@ -1,23 +0,0 @@
-title: Version 0.6 Coming Soon
-author: ryandahl
-date: Tue Oct 25 2011 15:26:23 GMT-0700 (PDT)
-status: publish
-category: Uncategorized
-slug: version-0-6
-
-Version 0.6.0 will be released next week. Please spend some time this
-week upgrading your code to v0.5.10. Report any API differences at https://github.com/joyent/node/wiki/API-changes-between-v0.4-and-v0.6
-or report a bug to us at http://github.com/joyent/node/issues
-if you hit problems.
-
-The API changes between v0.4.12 and v0.5.10 are 99% cosmetic, minor,
-and easy to fix. Most people are able to migrate their code in 10
-minutes. Don't fear.
-
-Once you've ported your code to v0.5.10 please help out by testing
-third party modules. Make bug reports. Encourage authors to publish
-new versions of their modules. Go through the list of modules at http://npmjs.org/ and try out random
-ones. This is especially encouraged of Windows users!
diff --git a/doc/blog/favicon.ico b/doc/blog/favicon.ico
deleted file mode 100644
index 03eaff0b59e..00000000000
Binary files a/doc/blog/favicon.ico and /dev/null differ
diff --git a/doc/blog/feature/streams2.md b/doc/blog/feature/streams2.md
deleted file mode 100644
index c1a135920b9..00000000000
--- a/doc/blog/feature/streams2.md
+++ /dev/null
@@ -1,851 +0,0 @@
-title: A New Streaming API for Node v0.10
-author: Isaac Z. Schlueter
-date: Fri Dec 21 00:45:13 UTC 2012
-slug: streams2
-category: feature
-
-**tl;dr**
-
-* Node streams are great, except for all the ways in which they're
- terrible.
-* A new Stream implementation is coming in 0.10, that has gotten the
- nickname "streams2".
-* Readable streams have a `read()` method that returns a buffer or
- null. (More documentation included below.)
-* `'data'` events, `pause()`, and `resume()` will still work as before
- (except that they'll actully work how you'd expect).
-* Old programs will **almost always** work without modification, but
- streams start out in a paused state, and need to be read from to be
- consumed.
-* **WARNING**: If you never add a `'data'` event handler, or call
- `resume()`, then it'll sit in a paused state forever and never
- emit `'end'`.
-
--------
-
-Throughout the life of Node, we've been gradually iterating on the
-ideal event-based API for handling data. Over time, this developed
-into the "Stream" interface that you see throughout Node's core
-modules and many of the modules in npm.
-
-Consistent interfaces increase the portability and reliability of our
-programs and libraries. Overall, the move from domain-specific events
-and methods towards a unified stream interface was a huge win.
-However, there are still several problems with Node's streams as of
-v0.8. In a nutshell:
-
-1. The `pause()` method doesn't pause. It is advisory-only. In
- Node's implementation, this makes things much simpler, but it's
- confusing to users, and doesn't do what it looks like it does.
-2. `'data'` events come right away (whether you're ready or not).
- This makes it unreasonably difficult to do common tasks like load a
- user's session before deciding how to handle their request.
-3. There is no way to consume a specific number of bytes, and then
- leave the rest for some other part of the program to deal with.
-4. It's unreasonably difficult to implement streams and get all the
- intricacies of pause, resume, write-buffering, and data events
- correct. The lack of shared classes mean that we all have to solve
- the same problems repeatedly, making similar mistakes and similar
- bugs.
-
-Common simple tasks should be easy, or we aren't doing our job.
-People often say that Node is better than most other platforms at this
-stuff, but in my opinion, that is less of a compliment and more of an
-indictment of the current state of software. Being better than the
-next guy isn't enough; we have to be the best imaginable. While they
-were a big step in the right direction, the Streams in Node up until
-now leave a lot wanting.
-
-So, just fix it, right?
-
-Well, we are sitting on the results of several years of explosive
-growth in the Node community, so any changes have to be made very
-carefully. If we break all the Node programs in 0.10, then no one
-will ever want to upgrade to 0.10, and it's all pointless. We had
-this conversation around 0.4, then again around 0.6, then again around
-0.8. Every time, the conclusion has been "Too much work, too hard to
-make backwards-compatible", and we always had more pressing problems
-to solve.
-
-In 0.10, we cannot put it off any longer. We've bitten the bullet and
-are making a significant change to the Stream implementation. You may
-have seen conversations on twitter or IRC or the mailing list about
-"streams2". I also gave [a talk in
-November](https://dl.dropbox.com/u/3685/presentations/streams2/streams2-ko.pdf)
-about this subject. A lot of node module authors have been involved
-with the development of streams2 (and of course the node core team).
-
-## streams2
-
-The feature is described pretty thoroughly in the documentation, so
-I'm including it below. Please read it, especially the section on
-"compatibility". There's a caveat there that is unfortunately
-unavoidable, but hopefully enough of an edge case that it's easily
-worked around.
-
-The first preview release with this change will be 0.9.4. I highly
-recommend trying this release and providing feedback before it lands
-in a stable version.
-
-As of writing this post, there are some known performance regressions,
-especially in the http module. We are fanatical about maintaining
-performance in Node.js, so of course this will have to be fixed before
-the v0.10 stable release. (Watch for a future blog post on the tools
-and techniques that have been useful in tracking down these issues.)
-
-There may be minor changes as necessary to fix bugs and improve
-performance, but the API at this point should be considered feature
-complete. It correctly does all the things we need it to do, it just
-doesn't do them quite well enough yet. As always, be wary of running
-unstable releases in production, of course, but I encourage you to try
-it out and see what you think. Especially, if you have tests that you
-can run on your modules and libraries, that would be extremely useful
-feedback.
-
---------
-
-# Stream
-
- Stability: 2 - Unstable
-
-A stream is an abstract interface implemented by various objects in
-Node. For example a request to an HTTP server is a stream, as is
-stdout. Streams are readable, writable, or both. All streams are
-instances of [EventEmitter][]
-
-You can load the Stream base classes by doing `require('stream')`.
-There are base classes provided for Readable streams, Writable
-streams, Duplex streams, and Transform streams.
-
-## Compatibility
-
-In earlier versions of Node, the Readable stream interface was
-simpler, but also less powerful and less useful.
-
-* Rather than waiting for you to call the `read()` method, `'data'`
- events would start emitting immediately. If you needed to do some
- I/O to decide how to handle data, then you had to store the chunks
- in some kind of buffer so that they would not be lost.
-* The `pause()` method was advisory, rather than guaranteed. This
- meant that you still had to be prepared to receive `'data'` events
- even when the stream was in a paused state.
-
-In Node v0.10, the Readable class described below was added. For
-backwards compatibility with older Node programs, Readable streams
-switch into "old mode" when a `'data'` event handler is added, or when
-the `pause()` or `resume()` methods are called. The effect is that,
-even if you are not using the new `read()` method and `'readable'`
-event, you no longer have to worry about losing `'data'` chunks.
-
-Most programs will continue to function normally. However, this
-introduces an edge case in the following conditions:
-
-* No `'data'` event handler is added.
-* The `pause()` and `resume()` methods are never called.
-
-For example, consider the following code:
-
-```javascript
-// WARNING! BROKEN!
-net.createServer(function(socket) {
-
- // we add an 'end' method, but never consume the data
- socket.on('end', function() {
- // It will never get here.
- socket.end('I got your message (but didnt read it)\n');
- });
-
-}).listen(1337);
-```
-
-In versions of node prior to v0.10, the incoming message data would be
-simply discarded. However, in Node v0.10 and beyond, the socket will
-remain paused forever.
-
-The workaround in this situation is to call the `resume()` method to
-trigger "old mode" behavior:
-
-```javascript
-// Workaround
-net.createServer(function(socket) {
-
- socket.on('end', function() {
- socket.end('I got your message (but didnt read it)\n');
- });
-
- // start the flow of data, discarding it.
- socket.resume();
-
-}).listen(1337);
-```
-
-In addition to new Readable streams switching into old-mode, pre-v0.10
-style streams can be wrapped in a Readable class using the `wrap()`
-method.
-
-## Class: stream.Readable
-
-
-
-A `Readable Stream` has the following methods, members, and events.
-
-Note that `stream.Readable` is an abstract class designed to be
-extended with an underlying implementation of the `_read(size)`
-method. (See below.)
-
-### new stream.Readable([options])
-
-* `options` {Object}
- * `highWaterMark` {Number} The maximum number of bytes to store in
- the internal buffer before ceasing to read from the underlying
- resource. Default=16kb
- * `encoding` {String} If specified, then buffers will be decoded to
- strings using the specified encoding. Default=null
- * `objectMode` {Boolean} Whether this stream should behave
- as a stream of objects. Meaning that stream.read(n) returns
- a single value instead of a Buffer of size n
-
-In classes that extend the Readable class, make sure to call the
-constructor so that the buffering settings can be properly
-initialized.
-
-### readable.\_read(size)
-
-* `size` {Number} Number of bytes to read asynchronously
-
-Note: **This function should NOT be called directly.** It should be
-implemented by child classes, and called by the internal Readable
-class methods only.
-
-All Readable stream implementations must provide a `_read` method
-to fetch data from the underlying resource.
-
-This method is prefixed with an underscore because it is internal to
-the class that defines it, and should not be called directly by user
-programs. However, you **are** expected to override this method in
-your own extension classes.
-
-When data is available, put it into the read queue by calling
-`readable.push(chunk)`. If `push` returns false, then you should stop
-reading. When `_read` is called again, you should start pushing more
-data.
-
-The `size` argument is advisory. Implementations where a "read" is a
-single call that returns data can use this to know how much data to
-fetch. Implementations where that is not relevant, such as TCP or
-TLS, may ignore this argument, and simply provide data whenever it
-becomes available. There is no need, for example to "wait" until
-`size` bytes are available before calling `stream.push(chunk)`.
-
-### readable.push(chunk)
-
-* `chunk` {Buffer | null | String} Chunk of data to push into the read queue
-* return {Boolean} Whether or not more pushes should be performed
-
-Note: **This function should be called by Readable implementors, NOT
-by consumers of Readable subclasses.** The `_read()` function will not
-be called again until at least one `push(chunk)` call is made. If no
-data is available, then you MAY call `push('')` (an empty string) to
-allow a future `_read` call, without adding any data to the queue.
-
-The `Readable` class works by putting data into a read queue to be
-pulled out later by calling the `read()` method when the `'readable'`
-event fires.
-
-The `push()` method will explicitly insert some data into the read
-queue. If it is called with `null` then it will signal the end of the
-data.
-
-In some cases, you may be wrapping a lower-level source which has some
-sort of pause/resume mechanism, and a data callback. In those cases,
-you could wrap the low-level source object by doing something like
-this:
-
-```javascript
-// source is an object with readStop() and readStart() methods,
-// and an `ondata` member that gets called when it has data, and
-// an `onend` member that gets called when the data is over.
-
-var stream = new Readable();
-
-source.ondata = function(chunk) {
- // if push() returns false, then we need to stop reading from source
- if (!stream.push(chunk))
- source.readStop();
-};
-
-source.onend = function() {
- stream.push(null);
-};
-
-// _read will be called when the stream wants to pull more data in
-// the advisory size argument is ignored in this case.
-stream._read = function(n) {
- source.readStart();
-};
-```
-
-### readable.unshift(chunk)
-
-* `chunk` {Buffer | null | String} Chunk of data to unshift onto the read queue
-* return {Boolean} Whether or not more pushes should be performed
-
-This is the corollary of `readable.push(chunk)`. Rather than putting
-the data at the *end* of the read queue, it puts it at the *front* of
-the read queue.
-
-This is useful in certain use-cases where a stream is being consumed
-by a parser, which needs to "un-consume" some data that it has
-optimistically pulled out of the source.
-
-```javascript
-// A parser for a simple data protocol.
-// The "header" is a JSON object, followed by 2 \n characters, and
-// then a message body.
-//
-// Note: This can be done more simply as a Transform stream. See below.
-
-function SimpleProtocol(source, options) {
- if (!(this instanceof SimpleProtocol))
- return new SimpleProtocol(options);
-
- Readable.call(this, options);
- this._inBody = false;
- this._sawFirstCr = false;
-
- // source is a readable stream, such as a socket or file
- this._source = source;
-
- var self = this;
- source.on('end', function() {
- self.push(null);
- });
-
- // give it a kick whenever the source is readable
- // read(0) will not consume any bytes
- source.on('readable', function() {
- self.read(0);
- });
-
- this._rawHeader = [];
- this.header = null;
-}
-
-SimpleProtocol.prototype = Object.create(
- Readable.prototype, { constructor: { value: SimpleProtocol }});
-
-SimpleProtocol.prototype._read = function(n) {
- if (!this._inBody) {
- var chunk = this._source.read();
-
- // if the source doesn't have data, we don't have data yet.
- if (chunk === null)
- return this.push('');
-
- // check if the chunk has a \n\n
- var split = -1;
- for (var i = 0; i < chunk.length; i++) {
- if (chunk[i] === 10) { // '\n'
- if (this._sawFirstCr) {
- split = i;
- break;
- } else {
- this._sawFirstCr = true;
- }
- } else {
- this._sawFirstCr = false;
- }
- }
-
- if (split === -1) {
- // still waiting for the \n\n
- // stash the chunk, and try again.
- this._rawHeader.push(chunk);
- this.push('');
- } else {
- this._inBody = true;
- var h = chunk.slice(0, split);
- this._rawHeader.push(h);
- var header = Buffer.concat(this._rawHeader).toString();
- try {
- this.header = JSON.parse(header);
- } catch (er) {
- this.emit('error', new Error('invalid simple protocol data'));
- return;
- }
- // now, because we got some extra data, unshift the rest
- // back into the read queue so that our consumer will see it.
- var b = chunk.slice(split);
- this.unshift(b);
-
- // and let them know that we are done parsing the header.
- this.emit('header', this.header);
- }
- } else {
- // from there on, just provide the data to our consumer.
- // careful not to push(null), since that would indicate EOF.
- var chunk = this._source.read();
- if (chunk) this.push(chunk);
- }
-};
-
-// Usage:
-var parser = new SimpleProtocol(source);
-// Now parser is a readable stream that will emit 'header'
-// with the parsed header data.
-```
-
-### readable.wrap(stream)
-
-* `stream` {Stream} An "old style" readable stream
-
-If you are using an older Node library that emits `'data'` events and
-has a `pause()` method that is advisory only, then you can use the
-`wrap()` method to create a Readable stream that uses the old stream
-as its data source.
-
-For example:
-
-```javascript
-var OldReader = require('./old-api-module.js').OldReader;
-var oreader = new OldReader;
-var Readable = require('stream').Readable;
-var myReader = new Readable().wrap(oreader);
-
-myReader.on('readable', function() {
- myReader.read(); // etc.
-});
-```
-
-### Event: 'readable'
-
-When there is data ready to be consumed, this event will fire.
-
-When this event emits, call the `read()` method to consume the data.
-
-### Event: 'end'
-
-Emitted when the stream has received an EOF (FIN in TCP terminology).
-Indicates that no more `'data'` events will happen. If the stream is
-also writable, it may be possible to continue writing.
-
-### Event: 'data'
-
-The `'data'` event emits either a `Buffer` (by default) or a string if
-`setEncoding()` was used.
-
-Note that adding a `'data'` event listener will switch the Readable
-stream into "old mode", where data is emitted as soon as it is
-available, rather than waiting for you to call `read()` to consume it.
-
-### Event: 'error'
-
-Emitted if there was an error receiving data.
-
-### Event: 'close'
-
-Emitted when the underlying resource (for example, the backing file
-descriptor) has been closed. Not all streams will emit this.
-
-### readable.setEncoding(encoding)
-
-Makes the `'data'` event emit a string instead of a `Buffer`. `encoding`
-can be `'utf8'`, `'utf16le'` (`'ucs2'`), `'ascii'`, or `'hex'`.
-
-The encoding can also be set by specifying an `encoding` field to the
-constructor.
-
-### readable.read([size])
-
-* `size` {Number | null} Optional number of bytes to read.
-* Return: {Buffer | String | null}
-
-Note: **This function SHOULD be called by Readable stream users.**
-
-Call this method to consume data once the `'readable'` event is
-emitted.
-
-The `size` argument will set a minimum number of bytes that you are
-interested in. If not set, then the entire content of the internal
-buffer is returned.
-
-If there is no data to consume, or if there are fewer bytes in the
-internal buffer than the `size` argument, then `null` is returned, and
-a future `'readable'` event will be emitted when more is available.
-
-Calling `stream.read(0)` will always return `null`, and will trigger a
-refresh of the internal buffer, but otherwise be a no-op.
-
-### readable.pipe(destination, [options])
-
-* `destination` {Writable Stream}
-* `options` {Object} Optional
- * `end` {Boolean} Default=true
-
-Connects this readable stream to `destination` WriteStream. Incoming
-data on this stream gets written to `destination`. Properly manages
-back-pressure so that a slow destination will not be overwhelmed by a
-fast readable stream.
-
-This function returns the `destination` stream.
-
-For example, emulating the Unix `cat` command:
-
- process.stdin.pipe(process.stdout);
-
-By default `end()` is called on the destination when the source stream
-emits `end`, so that `destination` is no longer writable. Pass `{ end:
-false }` as `options` to keep the destination stream open.
-
-This keeps `writer` open so that "Goodbye" can be written at the
-end.
-
- reader.pipe(writer, { end: false });
- reader.on("end", function() {
- writer.end("Goodbye\n");
- });
-
-Note that `process.stderr` and `process.stdout` are never closed until
-the process exits, regardless of the specified options.
-
-### readable.unpipe([destination])
-
-* `destination` {Writable Stream} Optional
-
-Undo a previously established `pipe()`. If no destination is
-provided, then all previously established pipes are removed.
-
-### readable.pause()
-
-Switches the readable stream into "old mode", where data is emitted
-using a `'data'` event rather than being buffered for consumption via
-the `read()` method.
-
-Ceases the flow of data. No `'data'` events are emitted while the
-stream is in a paused state.
-
-### readable.resume()
-
-Switches the readable stream into "old mode", where data is emitted
-using a `'data'` event rather than being buffered for consumption via
-the `read()` method.
-
-Resumes the incoming `'data'` events after a `pause()`.
-
-
-## Class: stream.Writable
-
-
-
-A `Writable` Stream has the following methods, members, and events.
-
-Note that `stream.Writable` is an abstract class designed to be
-extended with an underlying implementation of the
-`_write(chunk, encoding, cb)` method. (See below.)
-
-### new stream.Writable([options])
-
-* `options` {Object}
- * `highWaterMark` {Number} Buffer level when `write()` starts
- returning false. Default=16kb
- * `decodeStrings` {Boolean} Whether or not to decode strings into
- Buffers before passing them to `_write()`. Default=true
-
-In classes that extend the Writable class, make sure to call the
-constructor so that the buffering settings can be properly
-initialized.
-
-### writable.\_write(chunk, encoding, callback)
-
-* `chunk` {Buffer | String} The chunk to be written. Will always
- be a buffer unless the `decodeStrings` option was set to `false`.
-* `encoding` {String} If the chunk is a string, then this is the
- encoding type. Ignore chunk is a buffer. Note that chunk will
- **always** be a buffer unless the `decodeStrings` option is
- explicitly set to `false`.
-* `callback` {Function} Call this function (optionally with an error
- argument) when you are done processing the supplied chunk.
-
-All Writable stream implementations must provide a `_write` method to
-send data to the underlying resource.
-
-Note: **This function MUST NOT be called directly.** It should be
-implemented by child classes, and called by the internal Writable
-class methods only.
-
-Call the callback using the standard `callback(error)` pattern to
-signal that the write completed successfully or with an error.
-
-If the `decodeStrings` flag is set in the constructor options, then
-`chunk` may be a string rather than a Buffer, and `encoding` will
-indicate the sort of string that it is. This is to support
-implementations that have an optimized handling for certain string
-data encodings. If you do not explicitly set the `decodeStrings`
-option to `false`, then you can safely ignore the `encoding` argument,
-and assume that `chunk` will always be a Buffer.
-
-This method is prefixed with an underscore because it is internal to
-the class that defines it, and should not be called directly by user
-programs. However, you **are** expected to override this method in
-your own extension classes.
-
-
-### writable.write(chunk, [encoding], [callback])
-
-* `chunk` {Buffer | String} Data to be written
-* `encoding` {String} Optional. If `chunk` is a string, then encoding
- defaults to `'utf8'`
-* `callback` {Function} Optional. Called when this chunk is
- successfully written.
-* Returns {Boolean}
-
-Writes `chunk` to the stream. Returns `true` if the data has been
-flushed to the underlying resource. Returns `false` to indicate that
-the buffer is full, and the data will be sent out in the future. The
-`'drain'` event will indicate when the buffer is empty again.
-
-The specifics of when `write()` will return false, is determined by
-the `highWaterMark` option provided to the constructor.
-
-### writable.end([chunk], [encoding], [callback])
-
-* `chunk` {Buffer | String} Optional final data to be written
-* `encoding` {String} Optional. If `chunk` is a string, then encoding
- defaults to `'utf8'`
-* `callback` {Function} Optional. Called when the final chunk is
- successfully written.
-
-Call this method to signal the end of the data being written to the
-stream.
-
-### Event: 'drain'
-
-Emitted when the stream's write queue empties and it's safe to write
-without buffering again. Listen for it when `stream.write()` returns
-`false`.
-
-### Event: 'close'
-
-Emitted when the underlying resource (for example, the backing file
-descriptor) has been closed. Not all streams will emit this.
-
-### Event: 'finish'
-
-When `end()` is called and there are no more chunks to write, this
-event is emitted.
-
-### Event: 'pipe'
-
-* `source` {Readable Stream}
-
-Emitted when the stream is passed to a readable stream's pipe method.
-
-### Event 'unpipe'
-
-* `source` {Readable Stream}
-
-Emitted when a previously established `pipe()` is removed using the
-source Readable stream's `unpipe()` method.
-
-## Class: stream.Duplex
-
-
-
-A "duplex" stream is one that is both Readable and Writable, such as a
-TCP socket connection.
-
-Note that `stream.Duplex` is an abstract class designed to be
-extended with an underlying implementation of the `_read(size)`
-and `_write(chunk, encoding, callback)` methods as you would with a Readable or
-Writable stream class.
-
-Since JavaScript doesn't have multiple prototypal inheritance, this
-class prototypally inherits from Readable, and then parasitically from
-Writable. It is thus up to the user to implement both the lowlevel
-`_read(n)` method as well as the lowlevel `_write(chunk, encoding, cb)` method
-on extension duplex classes.
-
-### new stream.Duplex(options)
-
-* `options` {Object} Passed to both Writable and Readable
- constructors. Also has the following fields:
- * `allowHalfOpen` {Boolean} Default=true. If set to `false`, then
- the stream will automatically end the readable side when the
- writable side ends and vice versa.
-
-In classes that extend the Duplex class, make sure to call the
-constructor so that the buffering settings can be properly
-initialized.
-
-## Class: stream.Transform
-
-A "transform" stream is a duplex stream where the output is causally
-connected in some way to the input, such as a zlib stream or a crypto
-stream.
-
-There is no requirement that the output be the same size as the input,
-the same number of chunks, or arrive at the same time. For example, a
-Hash stream will only ever have a single chunk of output which is
-provided when the input is ended. A zlib stream will either produce
-much smaller or much larger than its input.
-
-Rather than implement the `_read()` and `_write()` methods, Transform
-classes must implement the `_transform()` method, and may optionally
-also implement the `_flush()` method. (See below.)
-
-### new stream.Transform([options])
-
-* `options` {Object} Passed to both Writable and Readable
- constructors.
-
-In classes that extend the Transform class, make sure to call the
-constructor so that the buffering settings can be properly
-initialized.
-
-### transform.\_transform(chunk, encoding, callback)
-
-* `chunk` {Buffer | String} The chunk to be transformed. Will always
- be a buffer unless the `decodeStrings` option was set to `false`.
-* `encoding` {String} If the chunk is a string, then this is the
- encoding type. (Ignore if `decodeStrings` chunk is a buffer.)
-* `callback` {Function} Call this function (optionally with an error
- argument) when you are done processing the supplied chunk.
-
-Note: **This function MUST NOT be called directly.** It should be
-implemented by child classes, and called by the internal Transform
-class methods only.
-
-All Transform stream implementations must provide a `_transform`
-method to accept input and produce output.
-
-`_transform` should do whatever has to be done in this specific
-Transform class, to handle the bytes being written, and pass them off
-to the readable portion of the interface. Do asynchronous I/O,
-process things, and so on.
-
-Call `transform.push(outputChunk)` 0 or more times to generate output
-from this input chunk, depending on how much data you want to output
-as a result of this chunk.
-
-Call the callback function only when the current chunk is completely
-consumed. Note that there may or may not be output as a result of any
-particular input chunk.
-
-This method is prefixed with an underscore because it is internal to
-the class that defines it, and should not be called directly by user
-programs. However, you **are** expected to override this method in
-your own extension classes.
-
-### transform.\_flush(callback)
-
-* `callback` {Function} Call this function (optionally with an error
- argument) when you are done flushing any remaining data.
-
-Note: **This function MUST NOT be called directly.** It MAY be implemented
-by child classes, and if so, will be called by the internal Transform
-class methods only.
-
-In some cases, your transform operation may need to emit a bit more
-data at the end of the stream. For example, a `Zlib` compression
-stream will store up some internal state so that it can optimally
-compress the output. At the end, however, it needs to do the best it
-can with what is left, so that the data will be complete.
-
-In those cases, you can implement a `_flush` method, which will be
-called at the very end, after all the written data is consumed, but
-before emitting `end` to signal the end of the readable side. Just
-like with `_transform`, call `transform.push(chunk)` zero or more
-times, as appropriate, and call `callback` when the flush operation is
-complete.
-
-This method is prefixed with an underscore because it is internal to
-the class that defines it, and should not be called directly by user
-programs. However, you **are** expected to override this method in
-your own extension classes.
-
-### Example: `SimpleProtocol` parser
-
-The example above of a simple protocol parser can be implemented much
-more simply by using the higher level `Transform` stream class.
-
-In this example, rather than providing the input as an argument, it
-would be piped into the parser, which is a more idiomatic Node stream
-approach.
-
-```javascript
-function SimpleProtocol(options) {
- if (!(this instanceof SimpleProtocol))
- return new SimpleProtocol(options);
-
- Transform.call(this, options);
- this._inBody = false;
- this._sawFirstCr = false;
- this._rawHeader = [];
- this.header = null;
-}
-
-SimpleProtocol.prototype = Object.create(
- Transform.prototype, { constructor: { value: SimpleProtocol }});
-
-SimpleProtocol.prototype._transform = function(chunk, encoding, done) {
- if (!this._inBody) {
- // check if the chunk has a \n\n
- var split = -1;
- for (var i = 0; i < chunk.length; i++) {
- if (chunk[i] === 10) { // '\n'
- if (this._sawFirstCr) {
- split = i;
- break;
- } else {
- this._sawFirstCr = true;
- }
- } else {
- this._sawFirstCr = false;
- }
- }
-
- if (split === -1) {
- // still waiting for the \n\n
- // stash the chunk, and try again.
- this._rawHeader.push(chunk);
- } else {
- this._inBody = true;
- var h = chunk.slice(0, split);
- this._rawHeader.push(h);
- var header = Buffer.concat(this._rawHeader).toString();
- try {
- this.header = JSON.parse(header);
- } catch (er) {
- this.emit('error', new Error('invalid simple protocol data'));
- return;
- }
- // and let them know that we are done parsing the header.
- this.emit('header', this.header);
-
- // now, because we got some extra data, emit this first.
- this.push(b);
- }
- } else {
- // from there on, just provide the data to our consumer as-is.
- this.push(b);
- }
- done();
-};
-
-var parser = new SimpleProtocol();
-source.pipe(parser)
-
-// Now parser is a readable stream that will emit 'header'
-// with the parsed header data.
-```
-
-
-## Class: stream.PassThrough
-
-This is a trivial implementation of a `Transform` stream that simply
-passes the input bytes across to the output. Its purpose is mainly
-for examples and testing, but there are occasionally use cases where
-it can come in handy.
-
-
-[EventEmitter]: http://nodejs.org/api/events.html#events_class_events_eventemitter
diff --git a/doc/blog/module/multi-server-continuous-deployment-with-fleet.md b/doc/blog/module/multi-server-continuous-deployment-with-fleet.md
deleted file mode 100644
index 7849ee410cd..00000000000
--- a/doc/blog/module/multi-server-continuous-deployment-with-fleet.md
+++ /dev/null
@@ -1,89 +0,0 @@
-title: multi-server continuous deployment with fleet
-author: Isaac Schlueter
-date: Wed May 02 2012 11:00:00 GMT-0700 (PDT)
-status: publish
-category: module
-slug: multi-server-continuous-deployment-with-fleet
-
- This is a guest post by James "SubStack" Halliday, originally posted on his blog, and reposted here with permission.
-
-Writing applications as a sequence of tiny services that all talk to each other over the network has many upsides, but it can be annoyingly tedious to get all the subsystems up and running.
-
-Running a seaport can help with getting all the services to talk to each other, but running the processes is another matter, especially when you have new code to push into production.
-
-fleet aims to make it really easy for anyone on your team to push new code from git to an armada of servers and manage all the processes in your stack.
-
-To start using fleet, just install the fleet command with npm:
-
-npm install -g fleet
-
-Then on one of your servers, start a fleet hub. From a fresh directory, give it a passphrase and a port to listen on:
-
-fleet hub --port=7000 --secret=beepboop
-
-Now fleet is listening on :7000 for commands and has started a git server on :7001 over http. There's no ssh keys or post commit hooks to configure, just run that command and you're ready to go!
-
-Next set up some worker drones to run your processes. You can have as many workers as you like on a single server but each worker should be run from a separate directory. Just do:
-
-fleet drone --hub=x.x.x.x:7000 --secret=beepboop
-
-where x.x.x.x is the address where the fleet hub is running. Spin up a few of these drones.
-
-Now navigate to the directory of the app you want to deploy. First set a remote so you don't need to type --hub and --secret all the time.
-
-fleet remote add default --hub=x.x.x.x:7000 --secret=beepboop
-
-Fleet just created a fleet.json file for you to save your settings.
-
-From the same app directory, to deploy your code just do:
-
-fleet deploy
-
-The deploy command does a git push to the fleet hub's git http server and then the hub instructs all the drones to pull from it. Your code gets checked out into a new directory on all the fleet drones every time you deploy.
-
-Because fleet is designed specifically for managing applications with lots of tiny services, the deploy command isn't tied to running any processes. Starting processes is up to the programmer but it's super simple. Just use the fleet spawn command:
-
-fleet spawn -- node server.js 8080
-
-By default fleet picks a drone at random to run the process on. You can specify which drone you want to run a particular process on with the --drone switch if it matters.
-
-Start a few processes across all your worker drones and then show what is running with the fleet ps command:
-
-fleet ps
-drone#3dfe17b8
-├─┬ pid#1e99f4
-│ ├── status: running
-│ ├── commit: webapp/1b8050fcaf8f1b02b9175fcb422644cb67dc8cc5
-│ └── command: node server.js 8888
-└─┬ pid#d7048a
- ├── status: running
- ├── commit: webapp/1b8050fcaf8f1b02b9175fcb422644cb67dc8cc5
- └── command: node server.js 8889
-
-Now suppose that you have new code to push out into production. By default, fleet lets you spin up new services without disturbing your existing services. If you fleet deploy again after checking in some new changes to git, the next time you fleet spawn a new process, that process will be spun up in a completely new directory based on the git commit hash. To stop a process, just use fleet stop.
-
-This approach lets you verify that the new services work before bringing down the old services. You can even start experimenting with heterogeneous and incremental deployment by hooking into a custom http proxy!
-
-Even better, if you use a service registry like seaport for managing the host/port tables, you can spin up new ad-hoc staging clusters all the time without disrupting the normal operation of your site before rolling out new code to users.
-
-Fleet has many more commands that you can learn about with its git-style manpage-based help system! Just do fleet help to get a list of all the commands you can run.
-
-fleet help
-Usage: fleet <command> [<args>]
-
-The commands are:
- deploy Push code to drones.
- drone Connect to a hub as a worker.
- exec Run commands on drones.
- hub Create a hub for drones to connect.
- monitor Show service events system-wide.
- ps List the running processes on the drones.
- remote Manage the set of remote hubs.
- spawn Run services on drones.
- stop Stop processes running on drones.
-
-For help about a command, try `fleet help `.
-
-npm install -g fleet and check out the code on github!
-
- diff --git a/doc/blog/module/service-logging-in-json-with-bunyan.md b/doc/blog/module/service-logging-in-json-with-bunyan.md
deleted file mode 100644
index 8a323c4aed2..00000000000
--- a/doc/blog/module/service-logging-in-json-with-bunyan.md
+++ /dev/null
@@ -1,337 +0,0 @@
-title: Service logging in JSON with Bunyan
-author: trentmick
-date: Wed Mar 28 2012 12:25:26 GMT-0700 (PDT)
-status: publish
-category: module
-slug: service-logging-in-json-with-bunyan
-
-
-
-
Service logs are gold, if you can mine them. We scan them for occasional debugging. Perhaps we grep them looking for errors or warnings, or setup an occasional nagios log regex monitor. If that. This is a waste of the best channel for data about a service.
-
-"Log. (Huh) What is it good for. Absolutely ..."
-
-
-- debugging
-- monitors tools that alert operators
-- non real-time analysis (business or operational analysis)
-- historical analysis
-
-
-These are what logs are good for. The current state of logging is barely adequate for the first of these. Doing reliable analysis, and even monitoring, of varied "printf-style" logs is a grueling or hacky task that most either don't bother with, fallback to paying someone else to do (viz. Splunk's great successes), or, for web sites, punt and use the plethora of JavaScript-based web analytics tools.
-
-Let's log in JSON. Let's format log records with a filter outside the app. Let's put more info in log records by not shoehorning into a printf-message. Debuggability can be improved. Monitoring and analysis can definitely be improved. Let's not write another regex-based parser, and use the time we've saved writing tools to collate logs from multiple nodes and services, to query structured logs (from all services, not just web servers), etc.
-
-At Joyent we use node.js for running many core services -- loosely coupled through HTTP REST APIs and/or AMQP. In this post I'll draw on experiences from my work on Joyent's SmartDataCenter product and observations of Joyent Cloud operations to suggest some improvements to service logging. I'll show the (open source) Bunyan logging library and tool that we're developing to improve the logging toolchain.
-
-
-
-# apache access log
-10.0.1.22 - - [15/Oct/2010:11:46:46 -0700] "GET /favicon.ico HTTP/1.1" 404 209
-fe80::6233:4bff:fe29:3173 - - [15/Oct/2010:11:46:58 -0700] "GET / HTTP/1.1" 200 44
-
-# apache error log
-[Fri Oct 15 11:46:46 2010] [error] [client 10.0.1.22] File does not exist: /Library/WebServer/Documents/favicon.ico
-[Fri Oct 15 11:46:58 2010] [error] [client fe80::6233:4bff:fe29:3173] File does not exist: /Library/WebServer/Documents/favicon.ico
-
-# Mac /var/log/secure.log
-Oct 14 09:20:56 banana loginwindow[41]: in pam_sm_authenticate(): Failed to determine Kerberos principal name.
-Oct 14 12:32:20 banana com.apple.SecurityServer[25]: UID 501 authenticated as user trentm (UID 501) for right 'system.privilege.admin'
-
-# an internal joyent agent log
-[2012-02-07 00:37:11.898] [INFO] AMQPAgent - Publishing success.
-[2012-02-07 00:37:11.910] [DEBUG] AMQPAgent - { req_id: '8afb8d99-df8e-4724-8535-3d52adaebf25',
- timestamp: '2012-02-07T00:37:11.898Z',
-
-# typical expressjs log output
-[Mon, 21 Nov 2011 20:52:11 GMT] 200 GET /foo (1ms)
-Blah, some other unstructured output to from a console.log call.
-
-
-What're we doing here? Five logs at random. Five different date formats. As Paul Querna points out we haven't improved log parsability in 20 years. Parsability is enemy number one. You can't use your logs until you can parse the records, and faced with the above the inevitable solution is a one-off regular expression.
-
-The current state of the art is various parsing libs, analysis tools and homebrew scripts ranging from grep to Perl, whose scope is limited to a few niches log formats.
-
-JSON for Logs
-
-JSON.parse() solves all that. Let's log in JSON. But it means a change in thinking: The first-level audience for log files shouldn't be a person, but a machine.
-
-That is not said lightly. The "Unix Way" of small focused tools lightly coupled with text output is important. JSON is less "text-y" than, e.g., Apache common log format. JSON makes grep and awk awkward. Using less directly on a log is handy.
-
-But not handy enough. That 80's pastel jumpsuit awkwardness you're feeling isn't the JSON, it's your tools. Time to find a json tool -- json is one, bunyan described below is another one. Time to learn your JSON library instead of your regex library: JavaScript, Python, Ruby, Java, Perl.
-
-Time to burn your log4j Layout classes and move formatting to the tools side. Creating a log message with semantic information and throwing that away to make a string is silly. The win at being able to trivially parse log records is huge. The possibilities at being able to add ad hoc structured information to individual log records is interesting: think program state metrics, think feeding to Splunk, or loggly, think easy audit logs.
-
-Introducing Bunyan
-
-Bunyan is a node.js module for logging in JSON and a bunyan CLI tool to view those logs.
-
-Logging with Bunyan basically looks like this:
-
-$ cat hi.js
-var Logger = require('bunyan');
-var log = new Logger({name: 'hello' /*, ... */});
-log.info("hi %s", "paul");
-
-
-And you'll get a log record like this:
-
-$ node hi.js
-{"name":"hello","hostname":"banana.local","pid":40026,"level":30,"msg":"hi paul","time":"2012-03-28T17:25:37.050Z","v":0}
-
-
-Pipe that through the bunyan tool that is part of the "node-bunyan" install to get more readable output:
-
-$ node hi.js | ./node_modules/.bin/bunyan # formatted text output
-[2012-02-07T18:50:18.003Z] INFO: hello/40026 on banana.local: hi paul
-
-$ node hi.js | ./node_modules/.bin/bunyan -j # indented JSON output
-{
- "name": "hello",
- "hostname": "banana.local",
- "pid": 40087,
- "level": 30,
- "msg": "hi paul",
- "time": "2012-03-28T17:26:38.431Z",
- "v": 0
-}
-
-
-Bunyan is log4j-like: create a Logger with a name, call log.info(...), etc. However it has no intention of reproducing much of the functionality of log4j. IMO, much of that is overkill for the types of services you'll tend to be writing with node.js.
-
-Longer Bunyan Example
-
-Let's walk through a bigger example to show some interesting things in Bunyan. We'll create a very small "Hello API" server using the excellent restify library -- which we used heavily here at Joyent. (Bunyan doesn't require restify at all, you can easily use Bunyan with Express or whatever.)
-
-You can follow along in https://github.com/trentm/hello-json-logging if you like. Note that I'm using the current HEAD of the bunyan and restify trees here, so details might change a bit. Prerequisite: a node 0.6.x installation.
-
-git clone https://github.com/trentm/hello-json-logging.git
-cd hello-json-logging
-make
-
-
-Bunyan Logger
-
-Our server first creates a Bunyan logger:
-
-var Logger = require('bunyan');
-var log = new Logger({
- name: 'helloapi',
- streams: [
- {
- stream: process.stdout,
- level: 'debug'
- },
- {
- path: 'hello.log',
- level: 'trace'
- }
- ],
- serializers: {
- req: Logger.stdSerializers.req,
- res: restify.bunyan.serializers.response,
- },
-});
-
-
-Every Bunyan logger must have a name. Unlike log4j, this is not a hierarchical dotted namespace. It is just a name field for the log records.
-
-Every Bunyan logger has one or more streams, to which log records are written. Here we've defined two: logging at DEBUG level and above is written to stdout, and logging at TRACE and above is appended to 'hello.log'.
-
-Bunyan has the concept of serializers: a registry of functions that know how to convert a JavaScript object for a certain log record field to a nice JSON representation for logging. For example, here we register the Logger.stdSerializers.req function to convert HTTP Request objects (using the field name "req") to JSON. More on serializers later.
-
-Restify Server
-
-Restify 1.x and above has bunyan support baked in. You pass in your Bunyan logger like this:
-
-var server = restify.createServer({
- name: 'Hello API',
- log: log // Pass our logger to restify.
-});
-
-
-Our simple API will have a single GET /hello?name=NAME endpoint:
-
-server.get({path: '/hello', name: 'SayHello'}, function(req, res, next) {
- var caller = req.params.name || 'caller';
- req.log.debug('caller is "%s"', caller);
- res.send({"hello": caller});
- return next();
-});
-
-
-If we run that, node server.js, and call the endpoint, we get the expected restify response:
-
-$ curl -iSs http://0.0.0.0:8080/hello?name=paul
-HTTP/1.1 200 OK
-Access-Control-Allow-Origin: *
-Access-Control-Allow-Headers: Accept, Accept-Version, Content-Length, Content-MD5, Content-Type, Date, X-Api-Version
-Access-Control-Expose-Headers: X-Api-Version, X-Request-Id, X-Response-Time
-Server: Hello API
-X-Request-Id: f6aaf942-c60d-4c72-8ddd-bada459db5e3
-Access-Control-Allow-Methods: GET
-Connection: close
-Content-Length: 16
-Content-MD5: Xmn3QcFXaIaKw9RPUARGBA==
-Content-Type: application/json
-Date: Tue, 07 Feb 2012 19:12:35 GMT
-X-Response-Time: 4
-
-{"hello":"paul"}
-
-
-Setup Server Logging
-
-Let's add two things to our server. First, we'll use the server.pre to hook into restify's request handling before routing where we'll log the request.
-
-server.pre(function (request, response, next) {
- request.log.info({req: request}, 'start'); // (1)
- return next();
-});
-
-
-This is the first time we've seen this log.info style with an object as the first argument. Bunyan logging methods (log.trace, log.debug, ...) all support an optional first object argument with extra log record fields:
-
-log.info(<object> fields, <string> msg, ...)
-
-
-Here we pass in the restify Request object, req. The "req" serializer we registered above will come into play here, but bear with me.
-
-Remember that we already had this debug log statement in our endpoint handler:
-
-req.log.debug('caller is "%s"', caller); // (2)
-
-
-Second, use the restify server after event to log the response:
-
-server.on('after', function (req, res, route) {
- req.log.info({res: res}, "finished"); // (3)
-});
-
-
-Log Output
-
-Now lets see what log output we get when somebody hits our API's endpoint:
-
-$ curl -iSs http://0.0.0.0:8080/hello?name=paul
-HTTP/1.1 200 OK
-...
-X-Request-Id: 9496dfdd-4ec7-4b59-aae7-3fed57aed5ba
-...
-
-{"hello":"paul"}
-
-
-Here is the server log:
-
-[trentm@banana:~/tm/hello-json-logging]$ node server.js
-... intro "listening at" log message elided ...
-{"name":"helloapi","hostname":"banana.local","pid":40341,"level":30,"req":{"method":"GET","url":"/hello?name=paul","headers":{"user-agent":"curl/7.19.7 (universal-apple-darwin10.0) libcurl/7.19.7 OpenSSL/0.9.8r zlib/1.2.3","host":"0.0.0.0:8080","accept":"*/*"},"remoteAddress":"127.0.0.1","remotePort":59831},"msg":"start","time":"2012-03-28T17:37:29.506Z","v":0}
-{"name":"helloapi","hostname":"banana.local","pid":40341,"route":"SayHello","req_id":"9496dfdd-4ec7-4b59-aae7-3fed57aed5ba","level":20,"msg":"caller is \"paul\"","time":"2012-03-28T17:37:29.507Z","v":0}
-{"name":"helloapi","hostname":"banana.local","pid":40341,"route":"SayHello","req_id":"9496dfdd-4ec7-4b59-aae7-3fed57aed5ba","level":30,"res":{"statusCode":200,"headers":{"access-control-allow-origin":"*","access-control-allow-headers":"Accept, Accept-Version, Content-Length, Content-MD5, Content-Type, Date, X-Api-Version","access-control-expose-headers":"X-Api-Version, X-Request-Id, X-Response-Time","server":"Hello API","x-request-id":"9496dfdd-4ec7-4b59-aae7-3fed57aed5ba","access-control-allow-methods":"GET","connection":"close","content-length":16,"content-md5":"Xmn3QcFXaIaKw9RPUARGBA==","content-type":"application/json","date":"Wed, 28 Mar 2012 17:37:29 GMT","x-response-time":3}},"msg":"finished","time":"2012-03-28T17:37:29.510Z","v":0}
-
-
-Lets look at each in turn to see what is interesting -- pretty-printed with node server.js | ./node_modules/.bin/bunyan -j:
-
-{ // (1)
- "name": "helloapi",
- "hostname": "banana.local",
- "pid": 40442,
- "level": 30,
- "req": {
- "method": "GET",
- "url": "/hello?name=paul",
- "headers": {
- "user-agent": "curl/7.19.7 (universal-apple-darwin10.0) libcurl/7.19.7 OpenSSL/0.9.8r zlib/1.2.3",
- "host": "0.0.0.0:8080",
- "accept": "*/*"
- },
- "remoteAddress": "127.0.0.1",
- "remotePort": 59834
- },
- "msg": "start",
- "time": "2012-03-28T17:39:44.880Z",
- "v": 0
-}
-
-
-Here we logged the incoming request with request.log.info({req: request}, 'start'). The use of the "req" field triggers the "req" serializer registered at Logger creation.
-
-Next the req.log.debug in our handler:
-
-{ // (2)
- "name": "helloapi",
- "hostname": "banana.local",
- "pid": 40442,
- "route": "SayHello",
- "req_id": "9496dfdd-4ec7-4b59-aae7-3fed57aed5ba",
- "level": 20,
- "msg": "caller is \"paul\"",
- "time": "2012-03-28T17:39:44.883Z",
- "v": 0
-}
-
-
-and the log of response in the "after" event:
-
-{ // (3)
- "name": "helloapi",
- "hostname": "banana.local",
- "pid": 40442,
- "route": "SayHello",
- "req_id": "9496dfdd-4ec7-4b59-aae7-3fed57aed5ba",
- "level": 30,
- "res": {
- "statusCode": 200,
- "headers": {
- "access-control-allow-origin": "*",
- "access-control-allow-headers": "Accept, Accept-Version, Content-Length, Content-MD5, Content-Type, Date, X-Api-Version",
- "access-control-expose-headers": "X-Api-Version, X-Request-Id, X-Response-Time",
- "server": "Hello API",
- "x-request-id": "9496dfdd-4ec7-4b59-aae7-3fed57aed5ba",
- "access-control-allow-methods": "GET",
- "connection": "close",
- "content-length": 16,
- "content-md5": "Xmn3QcFXaIaKw9RPUARGBA==",
- "content-type": "application/json",
- "date": "Wed, 28 Mar 2012 17:39:44 GMT",
- "x-response-time": 5
- }
- },
- "msg": "finished",
- "time": "2012-03-28T17:39:44.886Z",
- "v": 0
-}
-
-
-Two useful details of note here:
-
-
-The last two log messages include a "req_id" field (added to the req.log logger by restify). Note that this is the same UUID as the "X-Request-Id" header in the curl response. This means that if you use req.log for logging in your API handlers you will get an easy way to collate all logging for particular requests.
-
-If your's is an SOA system with many services, a best practice is to carry that X-Request-Id/req_id through your system to enable collating handling of a single top-level request.
The last two log messages include a "route" field. This tells you to which handler restify routed the request. While possibly useful for debugging, this can be very helpful for log-based monitoring of endpoints on a server.
-
-Recall that we also setup all logging to go the "hello.log" file. This was set at the TRACE level. Restify will log more detail of its operation at the trace level. See my "hello.log" for an example. The bunyan tool does a decent job of nicely formatting multiline messages and "req"/"res" keys (with color, not shown in the gist).
-
-This is logging you can use effectively.
-
-
-
-Bunyan is just one of many options for logging in node.js-land. Others (that I know of) supporting JSON logging are winston and logmagic. Paul Querna has an excellent post on using JSON for logging, which shows logmagic usage and also touches on topics like the GELF logging format, log transporting, indexing and searching.
-
-Final Thoughts
-
-Parsing challenges won't ever completely go away, but it can for your logs if you use JSON. Collating log records across logs from multiple nodes is facilitated by a common "time" field. Correlating logging across multiple services is enabled by carrying a common "req_id" (or equivalent) through all such logs.
-
-Separate log files for a single service is an anti-pattern. The typical Apache example of separate access and error logs is legacy, not an example to follow. A JSON log provides the structure necessary for tooling to easily filter for log records of a particular type.
-
-JSON logs bring possibilities. Feeding to tools like Splunk becomes easy. Ad hoc fields allow for a lightly spec'd comm channel from apps to other services: records with a "metric" could feed to statsd, records with a "loggly: true" could feed to loggly.com.
-
-Here I've described a very simple example of restify and bunyan usage for node.js-based API services with easy JSON logging. Restify provides a powerful framework for robust API services. Bunyan provides a light API for nice JSON logging and the beginnings of tooling to help consume Bunyan JSON logs.
-
-Update (29-Mar-2012): Fix styles somewhat for RSS readers.
diff --git a/doc/blog/nodejs-road-ahead.md b/doc/blog/nodejs-road-ahead.md
deleted file mode 100644
index 568530f214a..00000000000
--- a/doc/blog/nodejs-road-ahead.md
+++ /dev/null
@@ -1,52 +0,0 @@
-title: Node.js and the Road Ahead
-date: Thu Jan 16 15:00:00 PST 2014
-author: Timothy J Fontaine
-slug: nodejs-road-ahead
-
-As the new project lead for Node.js I am excited for our future, and want to
-give you an update on where we are.
-
-One of Node's major goals is to provide a small core, one that provides the
-right amount of surface area for consumers to achieve and innovate, without
-Node itself getting in the way. That ethos is alive and well, we're going to
-continue to provide a small, simple, and stable set of APIs that facilitate the
-amazing uses the community finds for Node. We're going to keep providing
-backward compatible APIs, so code you write today will continue to work on
-future versions of Node. And of course, performance tuning and bug fixing will
-always be an important part of every release cycle.
-
-The release of Node v0.12 is imminent, and a lot of significant work has gone
-into this release. There's streams3, a better keep alive agent for http, the vm
-module is now based on contextify, and significant performance work done in
-core features (Buffers, TLS, streams). We have a few APIs that are still being
-ironed out before we can feature freeze and branch (execSync, AsyncListeners,
-user definable instrumentation). We are definitely in the home stretch.
-
-But Node is far from done. In the short term there will be new releases of v8
-that we'll need to track, as well as integrating the new ABI stable C module
-interface. There are interesting language features that we can use to extend
-Node APIs (extend not replace). We need to write more tooling, we need to
-expose more interfaces to further enable innovation. We can explore
-functionality to embed Node in your existing project.
-
-The list can go on and on. Yet, Node is larger than the software itself. Node
-is also the community, the businesses, the ecosystems, and their related
-events. With that in mind there are things we can work to improve.
-
-The core team will be improving its procedures such that we can quickly and
-efficiently communicate with you. We want to provide high quality and timely
-responses to issues, describe our development roadmap, as well as provide our
-progress during each release cycle. We know you're interested in our plans for
-Node, and it's important we're able to provide that information. Communication
-should be bidirectional: we want to continue to receive feedback about how
-you're using Node, and what your pain points are.
-
-After the release of v0.12 we will facilitate the community to contribute and
-curate content for nodejs.org. Allowing the community to continue to invest in
-Node will ensure nodejs.org is an excellent starting point and the primary
-resource for tutorials, documentation, and materials regarding Node. We have an
-awesome and engaged community, and they're paramount to our success.
-
-I'm excited for Node's future, to see new and interesting use cases, and to
-continue to help businesses scale and innovate with Node. We have a lot we can
-accomplish together, and I look forward to seeing those results.
diff --git a/doc/blog/npm/2013-outage-postmortem.md b/doc/blog/npm/2013-outage-postmortem.md
deleted file mode 100644
index cd27e16c888..00000000000
--- a/doc/blog/npm/2013-outage-postmortem.md
+++ /dev/null
@@ -1,82 +0,0 @@
-date: Tue Nov 26 07:14:59 PST 2013
-author: Charlie Robbins
-title: Keeping The npm Registry Awesome
-slug: npm-post-mortem
-category: npm
-
-We know the availability and overall health of The npm Registry is paramount to everyone using Node.js as well as the larger JavaScript community and those of your using it for [some][browserify] [awesome][dotc] [projects][npm-rubygems] [and ideas][npm-python]. Between November 4th and November 15th 2013 The npm Registry had several hours of downtime over three distinct time periods:
-
-1. November 4th -- 16:30 to 15:00 UTC
-2. November 13th -- 15:00 to 19:30 UTC
-3. November 15th -- 15:30 to 18:00 UTC
-
-The root cause of these downtime was insufficient resources: both hardware and human. This is a full post-mortem where we will be look at how npmjs.org works, what went wrong, how we changed the previous architecture of The npm Registry to fix it, as well next steps we are taking to prevent this from happening again.
-
-All of the next steps require additional expenditure from Nodejitsu: both servers and labor. This is why along with this post-mortem we are announcing our [crowdfunding campaign: scalenpm.org](https://scalenpm.org)! Our goal is to raise enough funds so that Nodejitsu can continue to run The npm Registry as a free service for _you, the community._
-
-Please take a minute now to donate at [https://scalenpm.org](https://scalenpm.org)!
-
-## How does npmjs.org work?
-
-There are two distinct components that make up npmjs.org operated by different people:
-
-* **http://registry.npmjs.org**: The main CouchApp (Github: [isaacs/npmjs.org](https://github.com/isaacs/npmjs.org)) that stores both package tarballs and metadata. It is operated by Nodejitsu since we [acquired IrisCouch in May](https://www.nodejitsu.com/company/press/2013/05/22/iriscouch/). The primary system administrator is [Jason Smith](https://github.com/jhs), the current CTO at Nodejitsu, cofounder of IrisCouch, and the System Administrator of registry.npmjs.org since 2011.
-* **http://npmjs.org**: The npmjs website that you interact with using a web browser. It is a Node.js program (Github: [isaacs/npm-www](https://github.com/isaacs/npm-www)) maintained and operated by Isaac and running on a Joyent Public Cloud SmartMachine.
-
-Here is a high-level summary of the _old architecture:_
-
-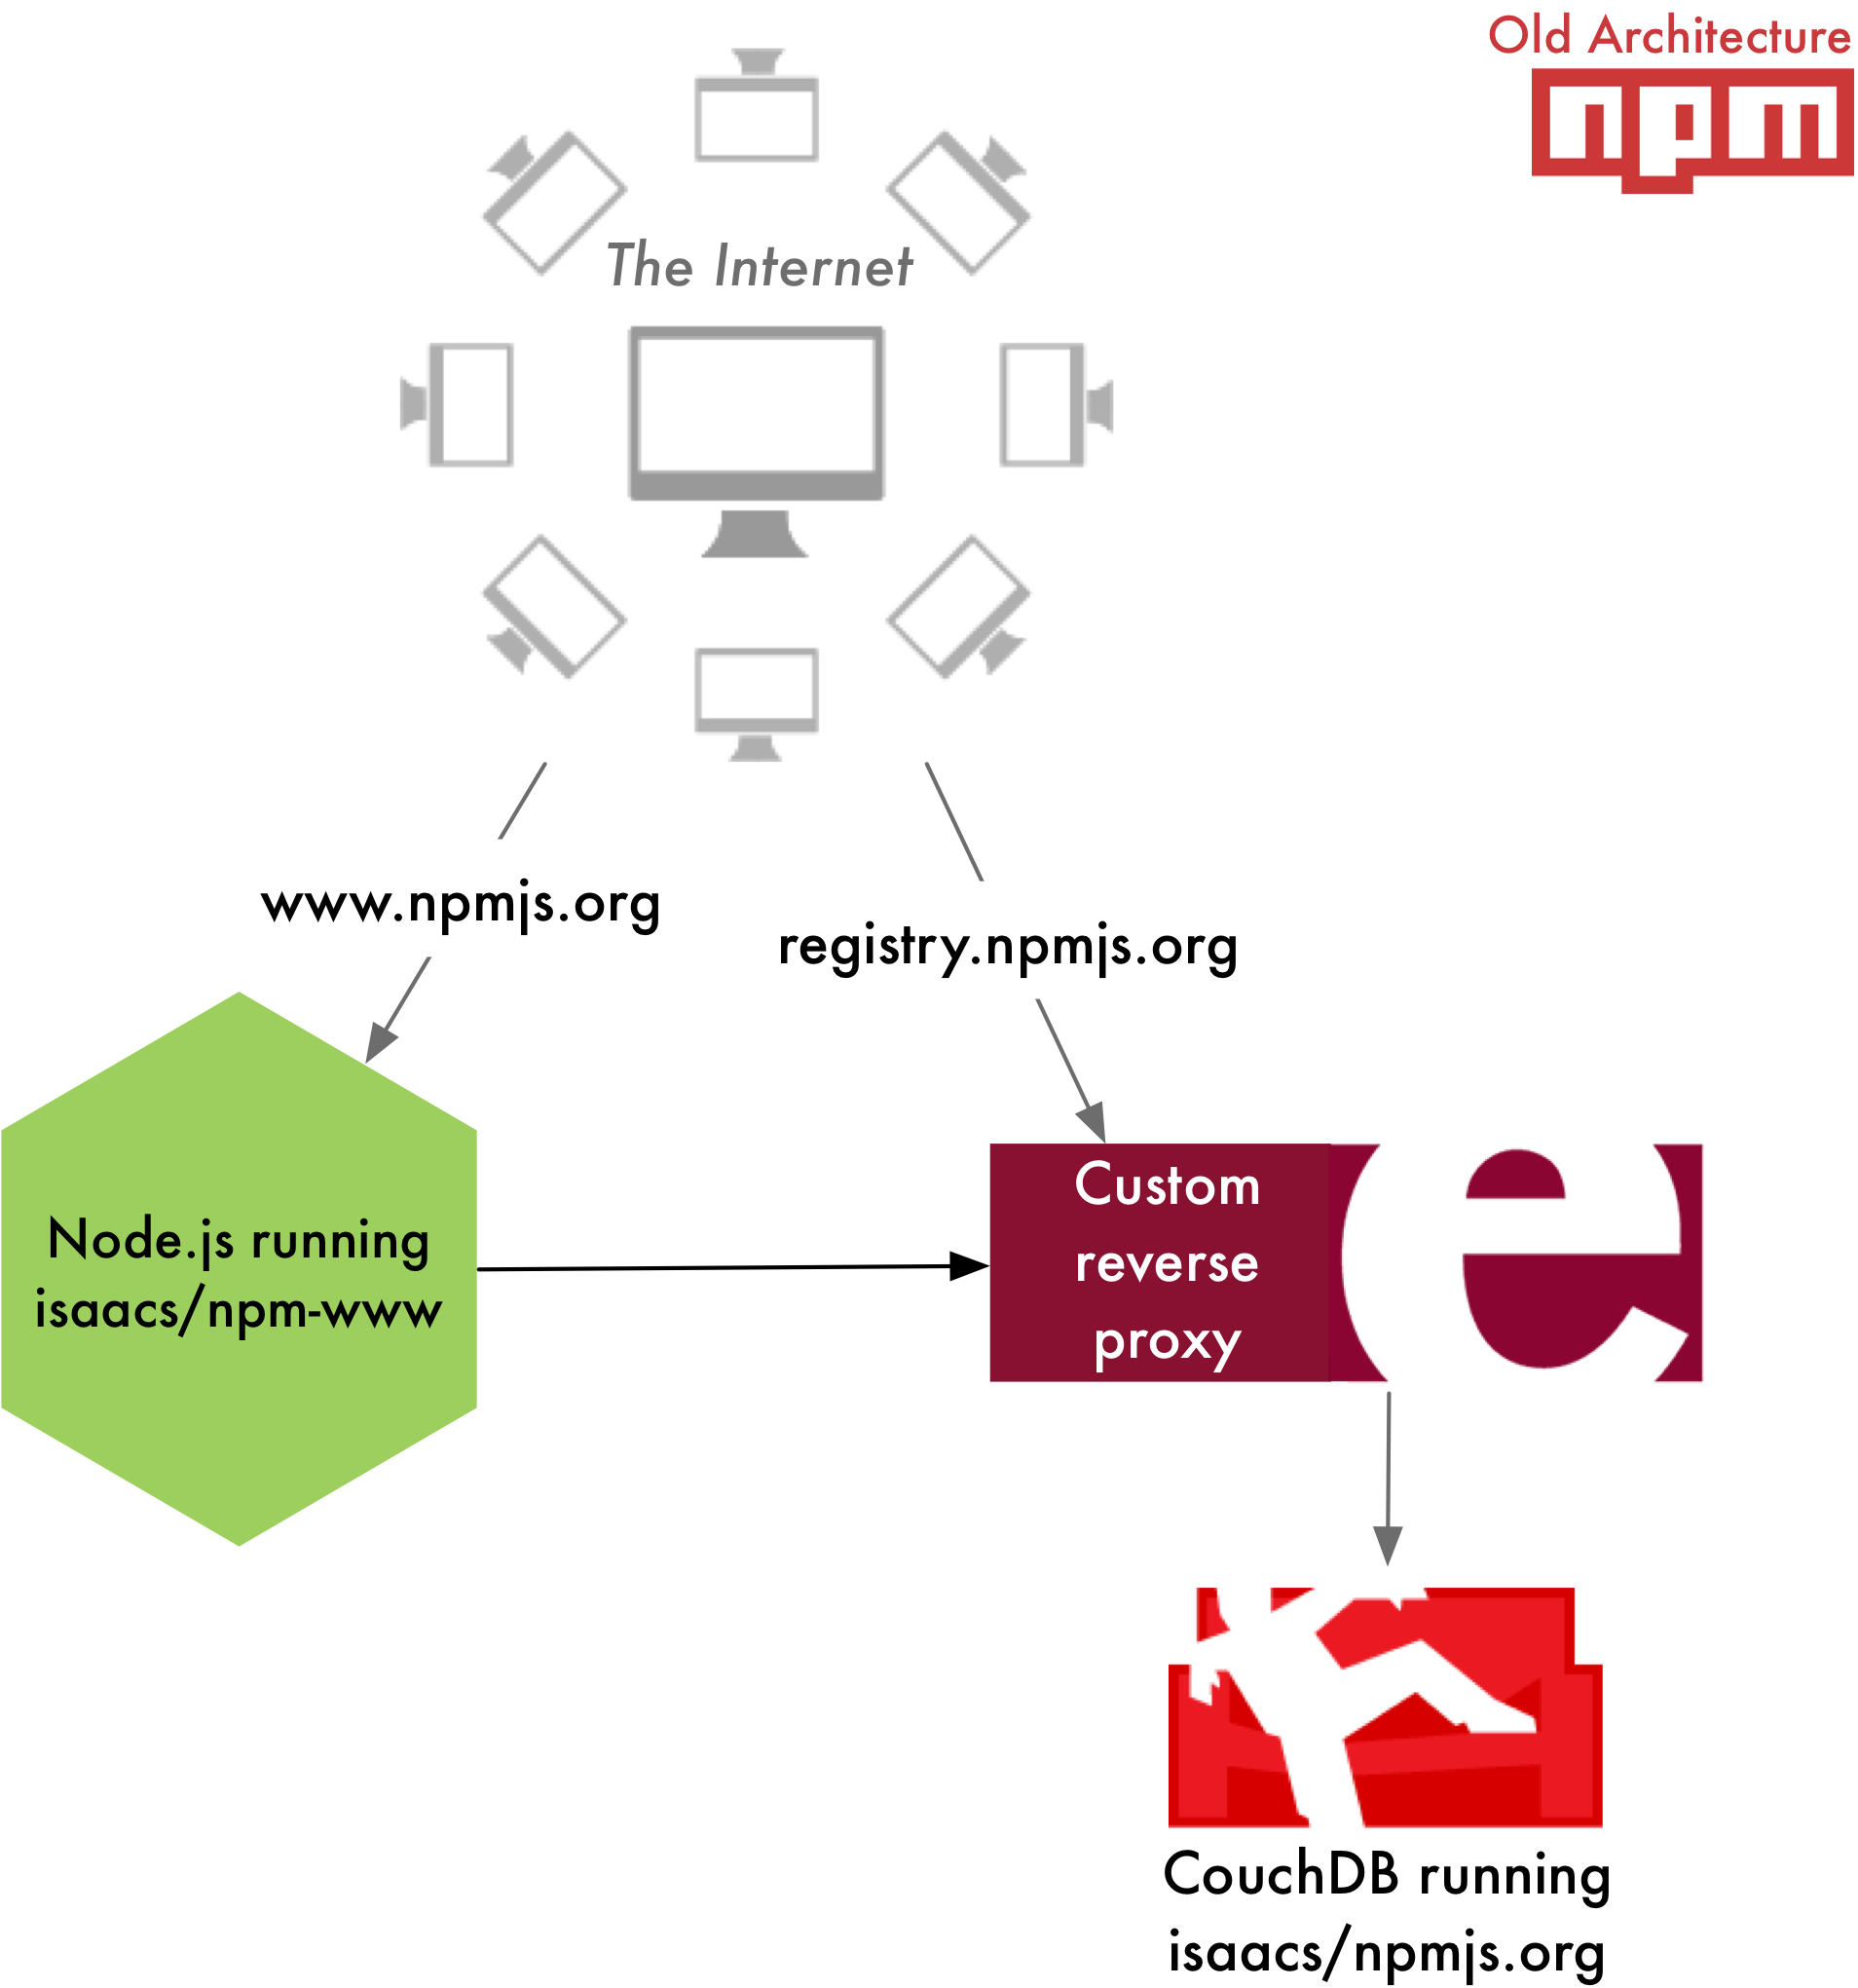 -
- _Diagram 1. Old npm architecture_
-
-
-## What went wrong and how was it fixed?
-
-As illustrated above, before November 13th, 2013, npm operated as a single CouchDB server with regular daily backups. We briefly ran a multi-master CouchDB setup after downtime back in August, but after reports that `npm login` no longer worked correctly we rolled back to a single CouchDB server. On both November 13th and November 15th CouchDB became unresponsive on requests to the `/registry` database while requests to all other databases (e.g. `/public_users`) remained responsive. Although the root cause of the CouchDB failures have yet to be determined given that only requests to `/registry` were slow and/or timed out we suspect it is related to the massive number of attachments stored in the registry.
-
-The incident on November 4th was ultimately resolved by a reboot and resize of the host machine, but when the same symptoms reoccured less than 10 days later additional steps were taken:
-
-1. The [registry was moved to another machine][ops-new-machine] of equal resources to exclude the possibility of a hardware issue.
-2. The [registry database itself][ops-compaction] was [compacted][compaction].
-
-When neither of these yielded a solution Jason Smith and I decided to move to a multi-master architecture with continuous replication illustrated below:
-
-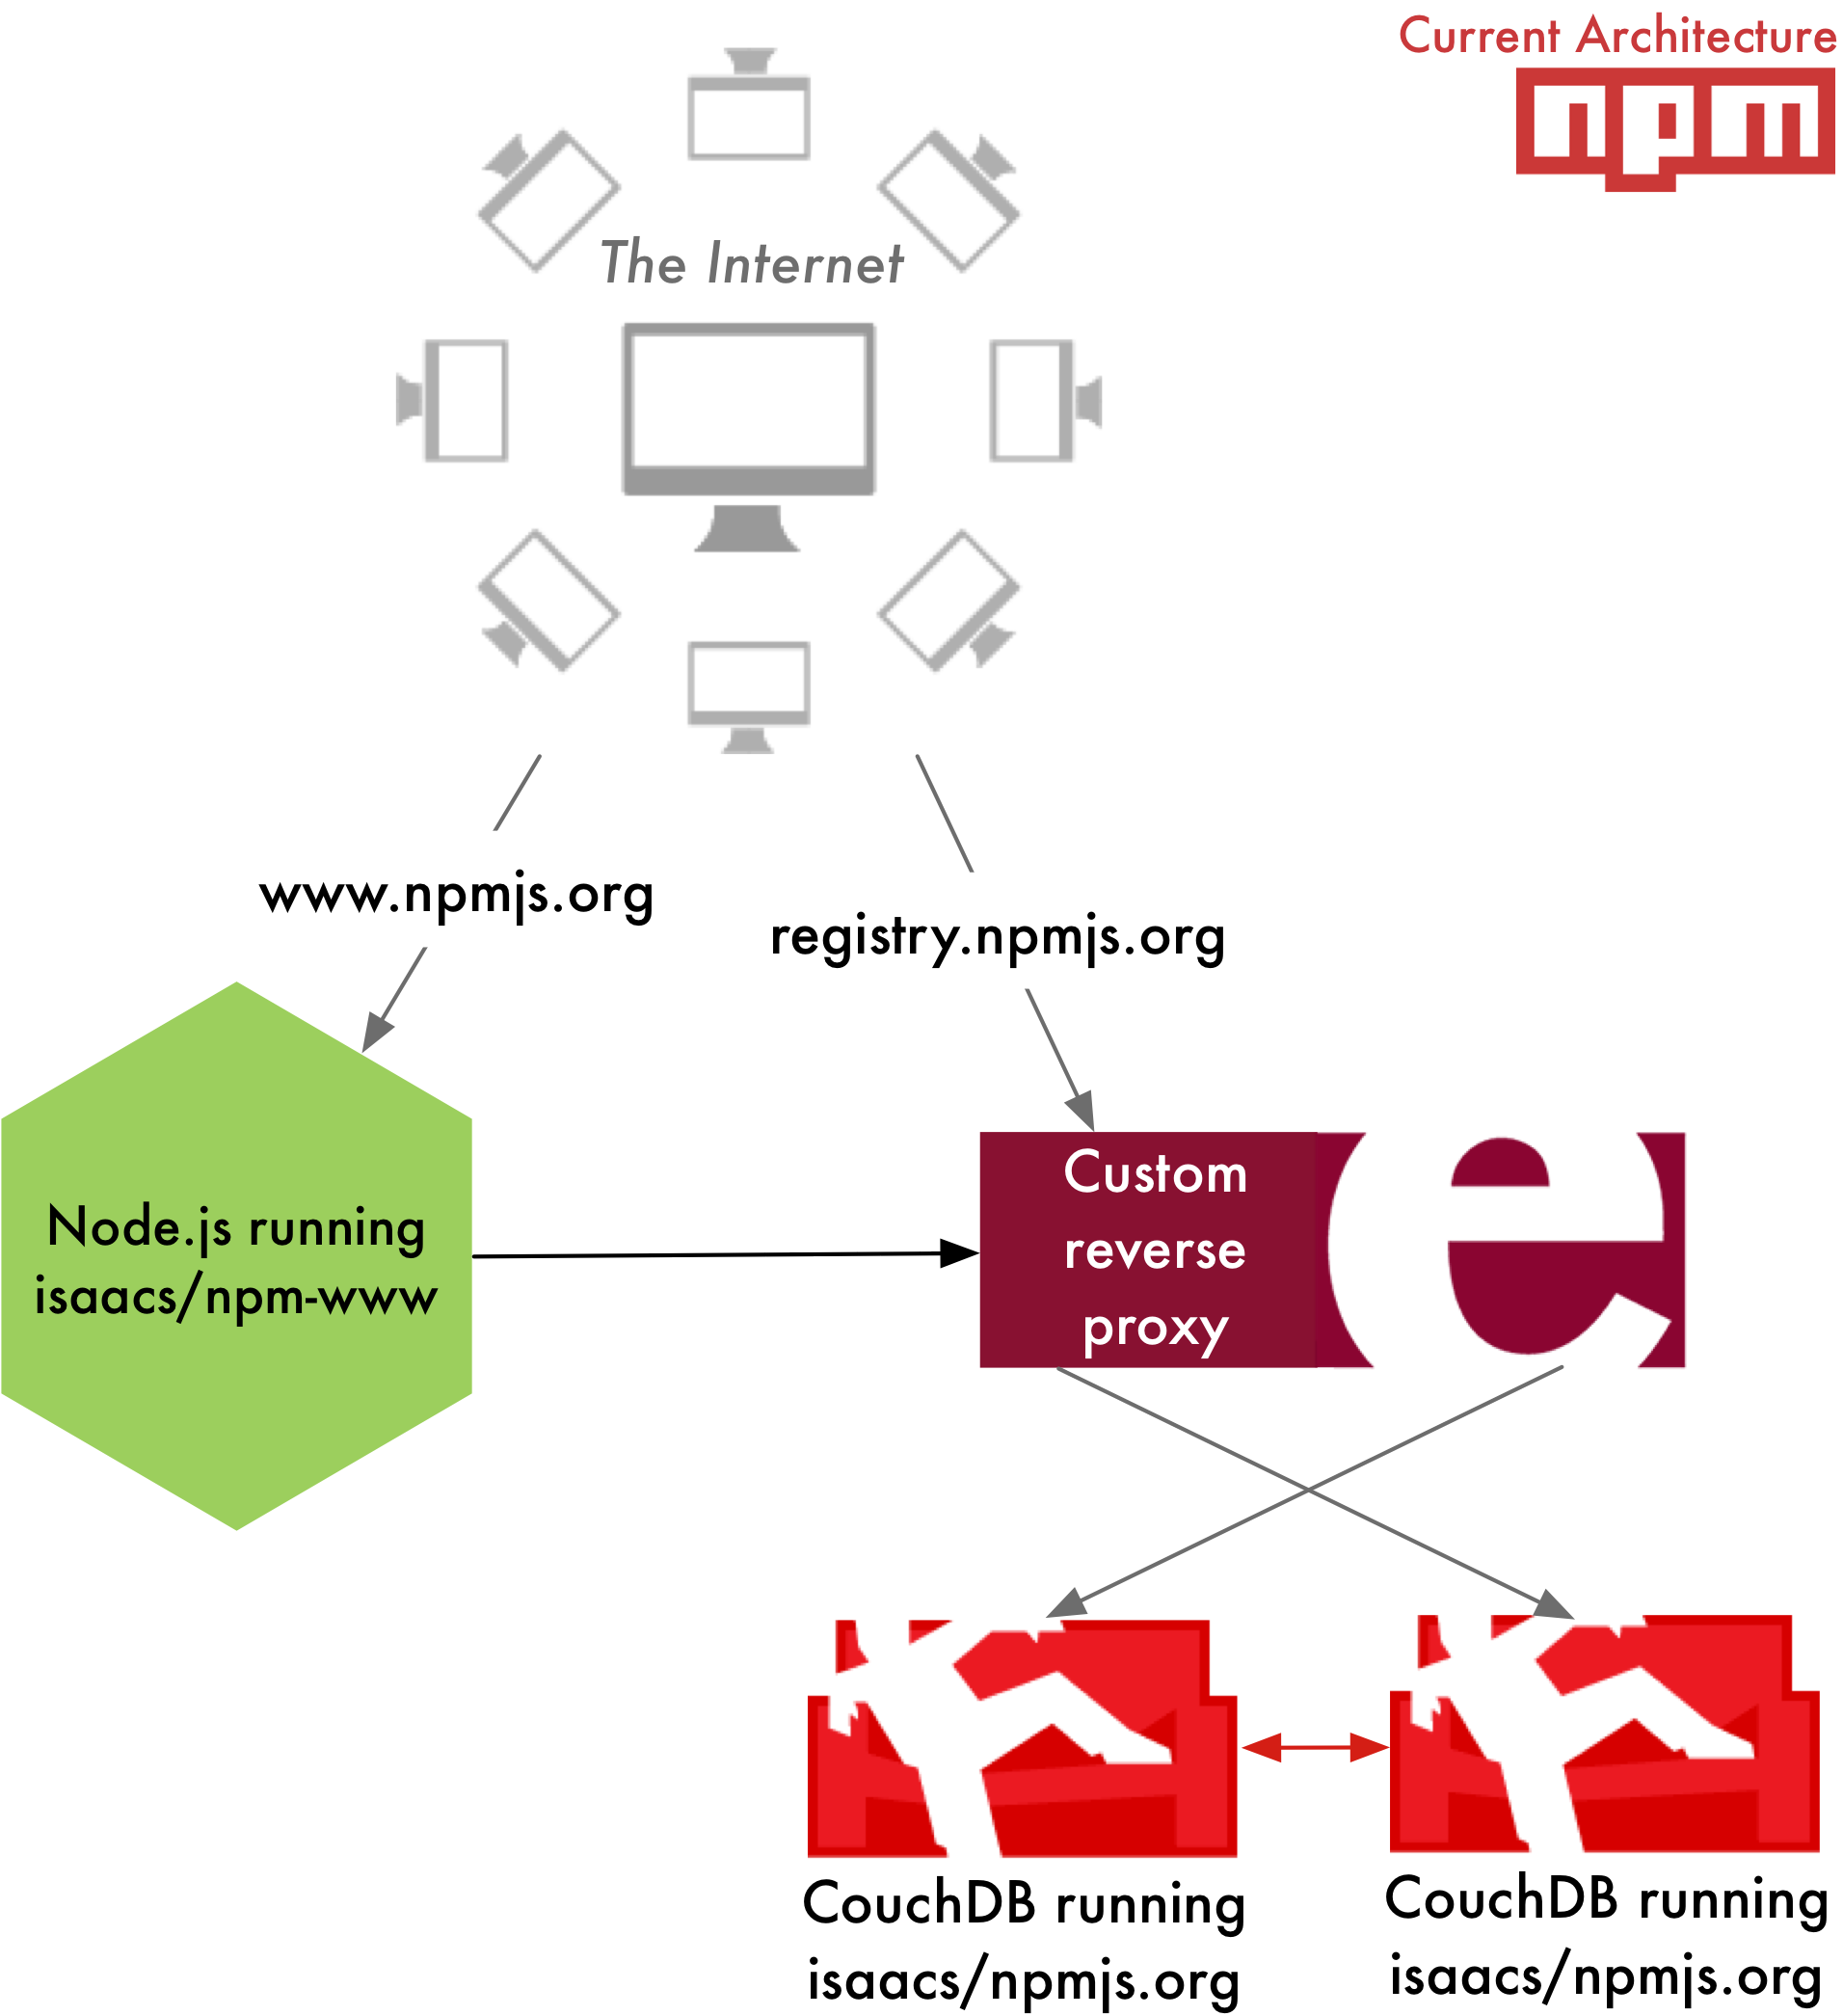 -
- _Diagram 2. Current npm architecture -- Red-lines denote continuous replication_
-
-
-This _should_ have been the end of our story but unfortunately our supervision logic did not function properly to restart the secondary master on the morning of November 15th. During this time we [moved briefly][ops-single-server] back to a single master architecture. Since then the secondary master has been closely monitored by the entire Nodejitsu operations team to ensure it's continued stability.
-
-## What is being done to prevent future incidents?
-
-The public npm registry simply cannot go down. **Ever.** We gained a lot of operational knowledge about The npm Registry and about CouchDB as a result of these outages. This new knowledge has made clear several steps that we need to take to prevent future downtime:
-
-1. **Always be in multi-master**: The multi-master CouchDB architecture we have setup will scale to more than just two CouchDB servers. _As npm grows we'll be able to add additional capacity!_
-2. **Decouple www.npmjs.org and registry.npmjs.org**: Right now www.npmjs.org still depends directly on registry.npmjs.org. We are planning to add an additional replica to the current npm architecture so that Isaac can more easily service requests to www.npmjs.org. That means it won't go down if the registry goes down.
-3. **Always have a spare replica**: We need have a hot spare replica running continuous replication from either to swap out when necessary. This is also important as we need to regularly run compaction on each master since the registry is growing ~10GB per week on disk.
-4. **Move attachments out of CouchDB**: Work has begun to move the package tarballs out of CouchDB and into [Joyent's Manta service](http://www.joyent.com/products/manta). Additionally, [MaxCDN](http://www.maxcdn.com/) has generously offered to provide CDN services for npm, once the tarballs are moved out of the registry database. This will help improve delivery speed, while dramatically reducing the file system I/O load on the CouchDB servers. Work is progressing slowly, because at each stage in the plan, we are making sure that current replication users are minimally impacted.
-
-When these new infrastructure components are in-place The npm Registry will look like this:
-
-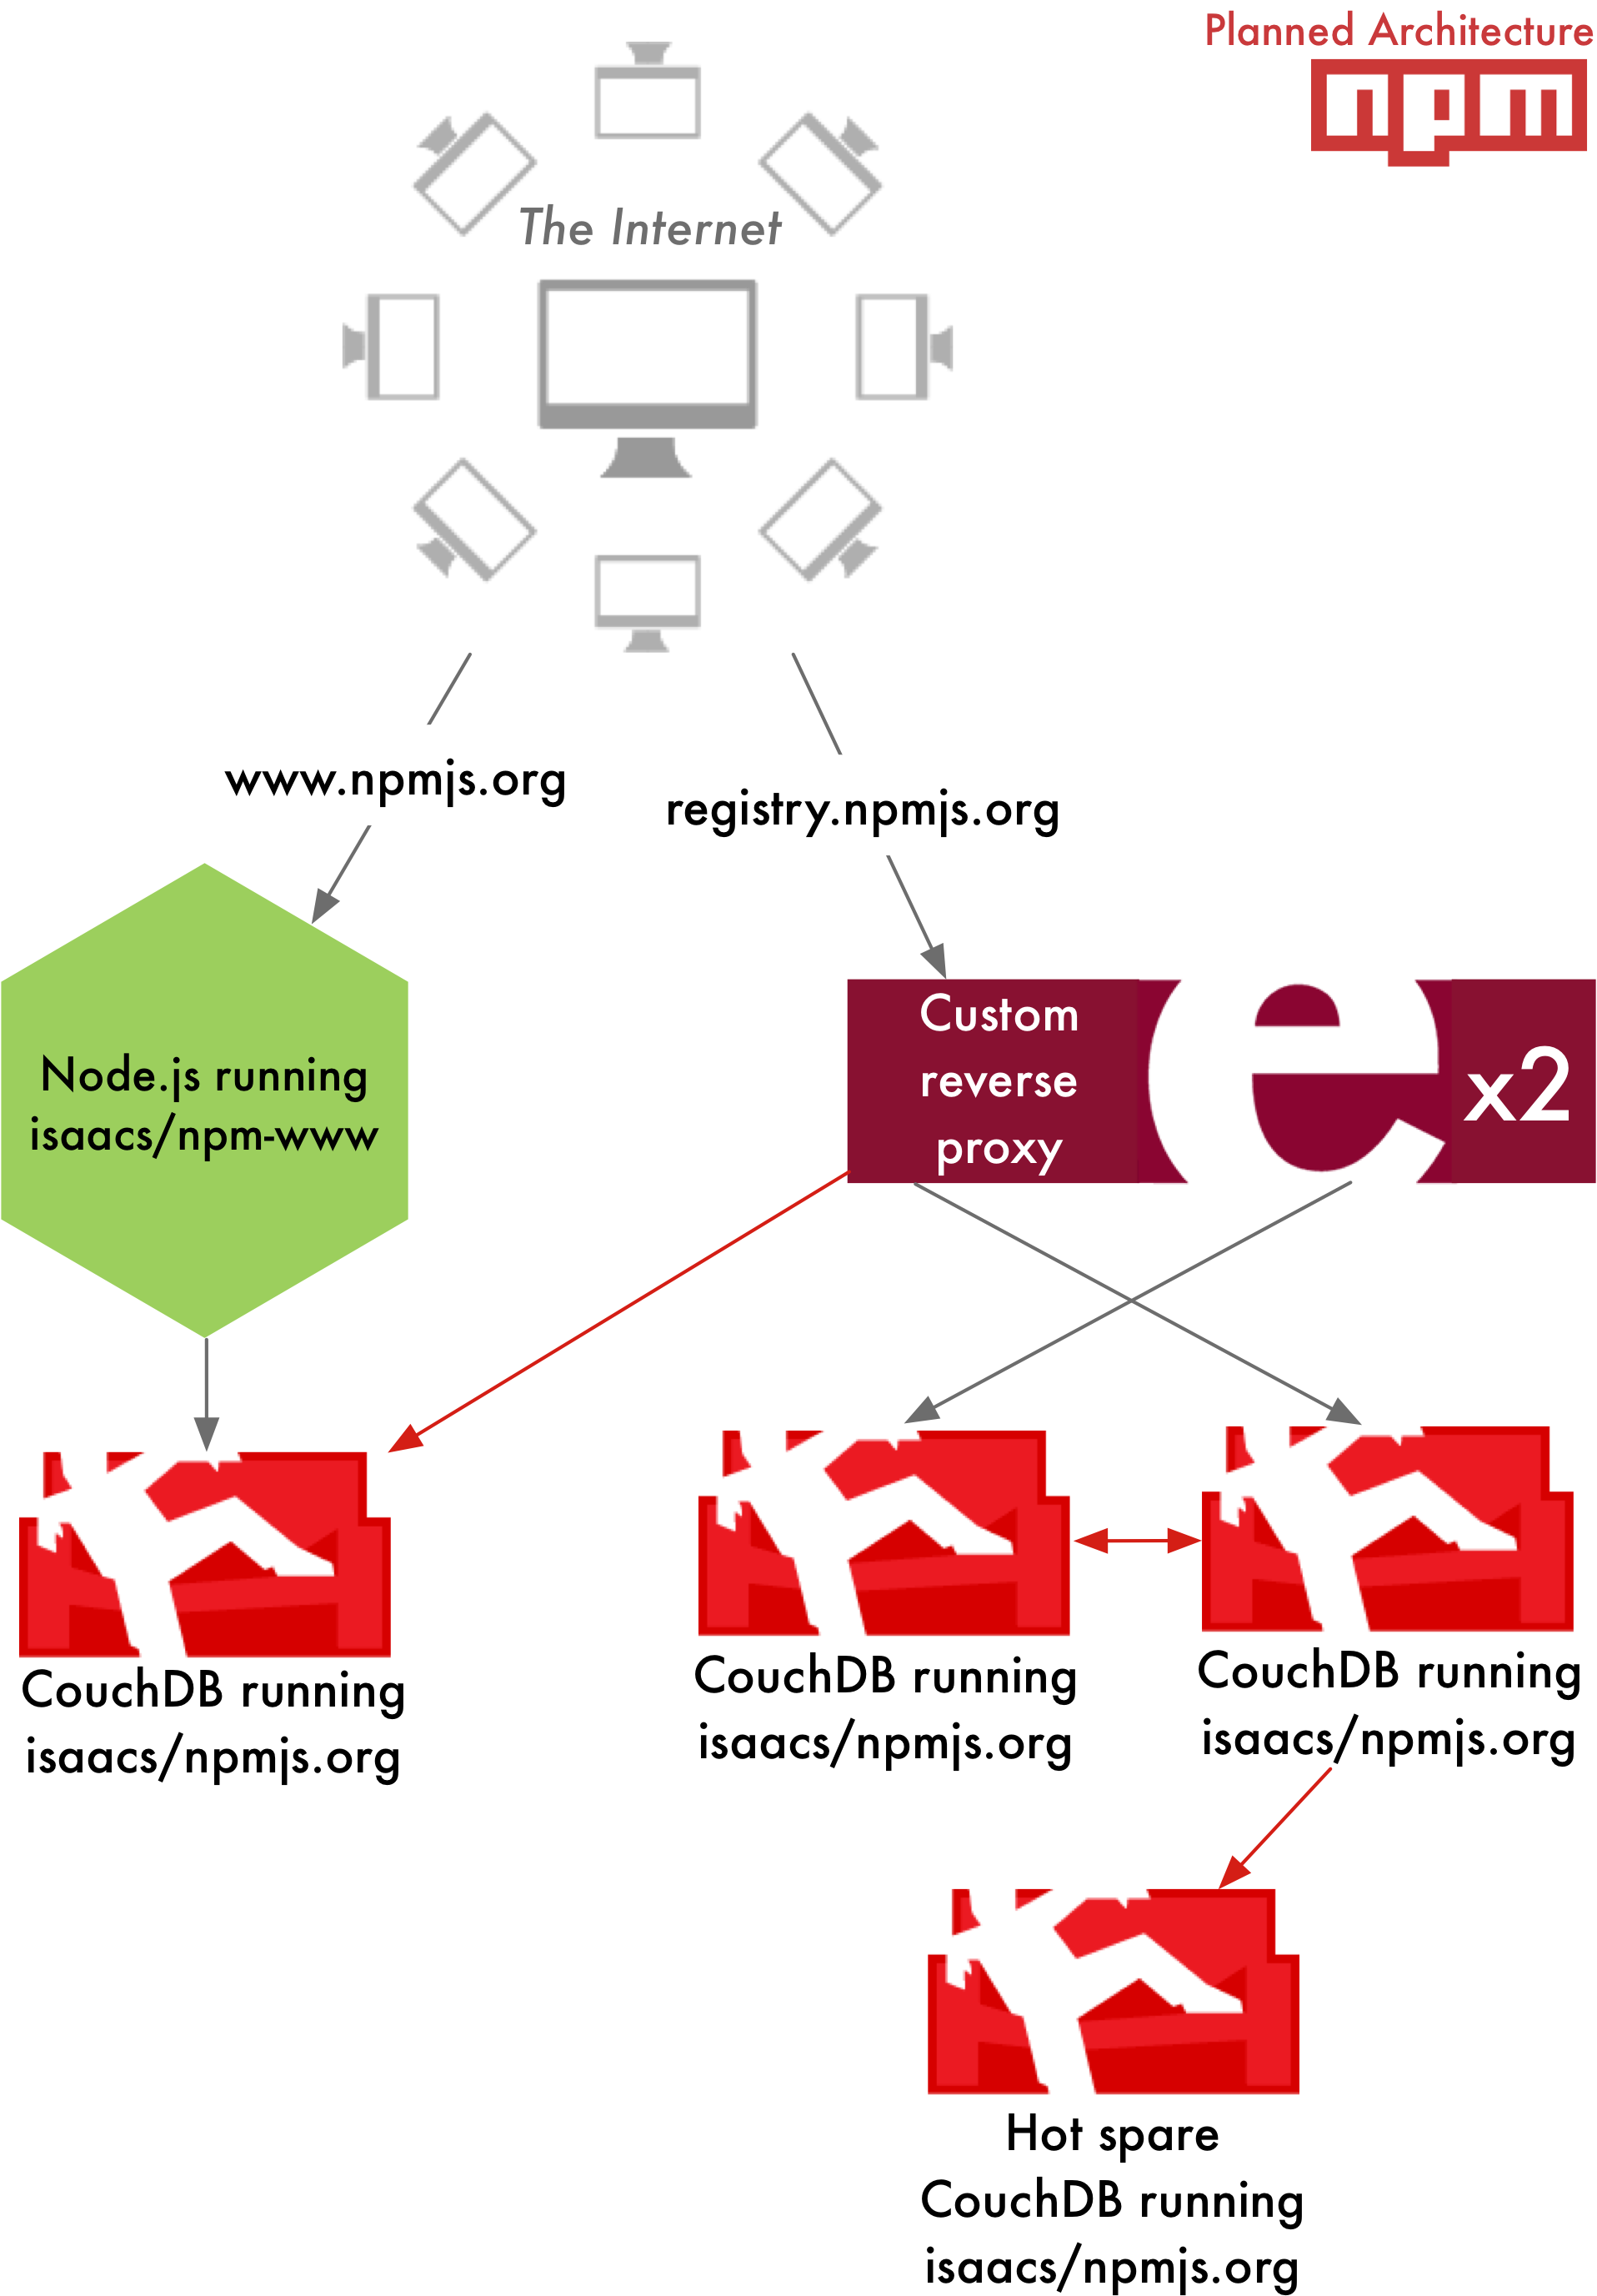 -
- _Diagram 3. Planned npm architecture -- Red-lines denote continuous replication_
-
-
-## You are npm! And we need your help!
-
-The npm Registry has had a 10x year. In November 2012 there were 13.5 million downloads. In October 2013 there were **114.6 million package downloads.** We're honored to have been a part of sustaining this growth for the community and we want to see it continue to grow to a billion package downloads a month and beyond.
-
-_**But we need your help!**_ All of these necessary improvements require more servers, more time from Nodejitsu staff and an overall increase to what we spend maintaining the public npm registry as a free service for the Node.js community.
-
-Please take a minute now to donate at [https://scalenpm.org](https://scalenpm.org)!
-
-[browserify]: http://browserify.org/
-[dotc]: https://github.com/substack/dotc
-[npm-rubygems]: http://andrew.ghost.io/emulating-node-js-modules-in-ruby/
-[npm-python]: https://twitter.com/__lucas/status/391688082573258753
-[ops-new-machine]: https://twitter.com/npmjs/status/400692071377276928
-[ops-compaction]: https://twitter.com/npmjs/status/400705715846643712
-[compaction]: http://wiki.apache.org/couchdb/Compaction
-[ops-single-server]: https://twitter.com/npmjs/status/401384681507016704
diff --git a/doc/blog/npm/managing-node-js-dependencies-with-shrinkwrap.md b/doc/blog/npm/managing-node-js-dependencies-with-shrinkwrap.md
deleted file mode 100644
index d48afab5a04..00000000000
--- a/doc/blog/npm/managing-node-js-dependencies-with-shrinkwrap.md
+++ /dev/null
@@ -1,167 +0,0 @@
-title: Managing Node.js Dependencies with Shrinkwrap
-author: Dave Pacheco
-date: Mon Feb 27 2012 10:51:59 GMT-0800 (PST)
-status: publish
-category: npm
-slug: managing-node-js-dependencies-with-shrinkwrap
-
-
-Photo by Luc Viatour (flickr)
-
-Managing dependencies is a fundamental problem in building complex software. The terrific success of github and npm have made code reuse especially easy in the Node world, where packages don't exist in isolation but rather as nodes in a large graph. The software is constantly changing (releasing new versions), and each package has its own constraints about what other packages it requires to run (dependencies). npm keeps track of these constraints, and authors express what kind of changes are compatible using semantic versioning, allowing authors to specify that their package will work with even future versions of its dependencies as long as the semantic versions are assigned properly.
-
-
-This does mean that when you "npm install" a package with dependencies, there's no guarantee that you'll get the same set of code now that you would have gotten an hour ago, or that you would get if you were to run it again an hour later. You may get a bunch of bug fixes now that weren't available an hour ago. This is great during development, where you want to keep up with changes upstream. It's not necessarily what you want for deployment, though, where you want to validate whatever bits you're actually shipping.
-
-
-Put differently, it's understood that all software changes incur some risk, and it's critical to be able to manage this risk on your own terms. Taking that risk in development is good because by definition that's when you're incorporating and testing software changes. On the other hand, if you're shipping production software, you probably don't want to take this risk when cutting a release candidate (i.e. build time) or when you actually ship (i.e. deploy time) because you want to validate whatever you ship.
-
-
-You can address a simple case of this problem by only depending on specific versions of packages, allowing no semver flexibility at all, but this falls apart when you depend on packages that don't also adopt the same principle. Many of us at Joyent started wondering: can we generalize this approach?
-
-
-Shrinkwrapping packages
-That brings us to npm shrinkwrap[1]:
-
-
-NAME
- npm-shrinkwrap -- Lock down dependency versions
-
-SYNOPSIS
- npm shrinkwrap
-
-DESCRIPTION
- This command locks down the versions of a package's dependencies so
- that you can control exactly which versions of each dependency will
- be used when your package is installed.
-Let's consider package A:
-
-
-{
- "name": "A",
- "version": "0.1.0",
- "dependencies": {
- "B": "<0.1.0"
- }
-}
-package B:
-
-
-{
- "name": "B",
- "version": "0.0.1",
- "dependencies": {
- "C": "<0.1.0"
- }
-}
-and package C:
-
-
-{
- "name": "C,
- "version": "0.0.1"
-}
-If these are the only versions of A, B, and C available in the registry, then a normal "npm install A" will install:
-
-
-A@0.1.0
-└─┬ B@0.0.1
- └── C@0.0.1
-Then if B@0.0.2 is published, then a fresh "npm install A" will install:
-
-
-A@0.1.0
-└─┬ B@0.0.2
- └── C@0.0.1
-assuming the new version did not modify B's dependencies. Of course, the new version of B could include a new version of C and any number of new dependencies. As we said before, if A's author doesn't want that, she could specify a dependency on B@0.0.1. But if A's author and B's author are not the same person, there's no way for A's author to say that she does not want to pull in newly published versions of C when B hasn't changed at all.
-
-
-In this case, A's author can use
-
-
-# npm shrinkwrap
-This generates npm-shrinkwrap.json, which will look something like this:
-
-
-{
- "name": "A",
- "dependencies": {
- "B": {
- "version": "0.0.1",
- "dependencies": {
- "C": { "version": "0.1.0" }
- }
- }
- }
-}
-The shrinkwrap command has locked down the dependencies based on what's currently installed in node_modules. When "npm install" installs a package with a npm-shrinkwrap.json file in the package root, the shrinkwrap file (rather than package.json files) completely drives the installation of that package and all of its dependencies (recursively). So now the author publishes A@0.1.0, and subsequent installs of this package will use B@0.0.1 and C@0.1.0, regardless the dependencies and versions listed in A's, B's, and C's package.json files. If the authors of B and C publish new versions, they won't be used to install A because the shrinkwrap refers to older versions. Even if you generate a new shrinkwrap, it will still reference the older versions, since "npm shrinkwrap" uses what's installed locally rather than what's available in the registry.
-
-
-Using shrinkwrapped packages
-Using a shrinkwrapped package is no different than using any other package: you can "npm install" it by hand, or add a dependency to your package.json file and "npm install" it.
-
-
-Building shrinkwrapped packages
-To shrinkwrap an existing package:
-
-
-
-- Run "npm install" in the package root to install the current versions of all dependencies.
-- Validate that the package works as expected with these versions.
-- Run "npm shrinkwrap", add npm-shrinkwrap.json to git, and publish your package.
-
-To add or update a dependency in a shrinkwrapped package:
-
-
-
-- Run "npm install" in the package root to install the current versions of all dependencies.
-- Add or update dependencies. "npm install" each new or updated package individually and then update package.json.
-- Validate that the package works as expected with the new dependencies.
-- Run "npm shrinkwrap", commit the new npm-shrinkwrap.json, and publish your package.
-
-You can still use npm outdated(1) to view which dependencies have newer versions available.
-
-
-For more details, check out the full docs on npm shrinkwrap, from which much of the above is taken.
-
-
-Why not just check node_modules into git?
-One previously proposed solution is to "npm install" your dependencies during development and commit the results into source control. Then you deploy your app from a specific git SHA knowing you've got exactly the same bits that you tested in development. This does address the problem, but it has its own issues: for one, binaries are tricky because you need to "npm install" them to get their sources, but this builds the [system-dependent] binary too. You can avoid checking in the binaries and use "npm rebuild" at build time, but we've had a lot of difficulty trying to do this.[2] At best, this is second-class treatment for binary modules, which are critical for many important types of Node applications.[3]
-
-
-Besides the issues with binary modules, this approach just felt wrong to many of us. There's a reason we don't check binaries into source control, and it's not just because they're platform-dependent. (After all, we could build and check in binaries for all supported platforms and operating systems.) It's because that approach is error-prone and redundant: error-prone because it introduces a new human failure mode where someone checks in a source change but doesn't regenerate all the binaries, and redundant because the binaries can always be built from the sources alone. An important principle of software version control is that you don't check in files derived directly from other files by a simple transformation.[4] Instead, you check in the original sources and automate the transformations via the build process.
-
-
-Dependencies are just like binaries in this regard: they're files derived from a simple transformation of something else that is (or could easily be) already available: the name and version of the dependency. Checking them in has all the same problems as checking in binaries: people could update package.json without updating the checked-in module (or vice versa). Besides that, adding new dependencies has to be done by hand, introducing more opportunities for error (checking in the wrong files, not checking in certain files, inadvertently changing files, and so on). Our feeling was: why check in this whole dependency tree (and create a mess for binary add-ons) when we could just check in the package name and version and have the build process do the rest?
-
-
-Finally, the approach of checking in node_modules doesn't really scale for us. We've got at least a dozen repos that will use restify, and it doesn't make sense to check that in everywhere when we could instead just specify which version each one is using. There's another principle at work here, which is separation of concerns: each repo specifies what it needs, while the build process figures out where to get it.
-
-
-What if an author republishes an existing version of a package?
-We're not suggesting deploying a shrinkwrapped package directly and running "npm install" to install from shrinkwrap in production. We already have a build process to deal with binary modules and other automateable tasks. That's where we do the "npm install". We tar up the result and distribute the tarball. Since we test each build before shipping, we won't deploy something we didn't test.
-
-
-It's still possible to pick up newly published versions of existing packages at build time. We assume force publish is not that common in the first place, let alone force publish that breaks compatibility. If you're worried about this, you can use git SHAs in the shrinkwrap or even consider maintaining a mirror of the part of the npm registry that you use and require human confirmation before mirroring unpublishes.
-
-
-Final thoughts
-Of course, the details of each use case matter a lot, and the world doesn't have to pick just one solution. If you like checking in node_modules, you should keep doing that. We've chosen the shrinkwrap route because that works better for us.
-
-
-It's not exactly news that Joyent is heavy on Node. Node is the heart of our SmartDataCenter (SDC) product, whose public-facing web portal, public API, Cloud Analytics, provisioning, billing, heartbeating, and other services are all implemented in Node. That's why it's so important to us to have robust components (like logging and REST) and tools for understanding production failures postmortem, profile Node apps in production, and now managing Node dependencies. Again, we're interested to hear feedback from others using these tools.
-
-
-
-Dave Pacheco blogs at dtrace.org.
-
-[1] Much of this section is taken directly from the "npm shrinkwrap" documentation.
-
-
-[2] We've had a lot of trouble with checking in node_modules with binary dependencies. The first problem is figuring out exactly which files not to check in (.o, .node, .dynlib, .so, *.a, ...). When Mark went to apply this to one of our internal services, the "npm rebuild" step blew away half of the dependency tree because it ran "make clean", which in dependency ldapjs brings the repo to a clean slate by blowing away its dependencies. Later, a new (but highly experienced) engineer on our team was tasked with fixing a bug in our Node-based DHCP server. To fix the bug, we went with a new dependency. He tried checking in node_modules, which added 190,000 lines of code (to this repo that was previously a few hundred LOC). And despite doing everything he could think of to do this correctly and test it properly, the change broke the build because of the binary modules. So having tried this approach a few times now, it appears quite difficult to get right, and as I pointed out above, the lack of actual documentation and real world examples suggests others either aren't using binary modules (which we know isn't true) or haven't had much better luck with this approach.
-
-
-[3] Like a good Node-based distributed system, our architecture uses lots of small HTTP servers. Each of these serves a REST API using restify. restify uses the binary module node-dtrace-provider, which gives each of our services deep DTrace-based observability for free. So literally almost all of our components are or will soon be depending on a binary add-on. Additionally, the foundation of Cloud Analytics are a pair of binary modules that extract data from DTrace and kstat. So this isn't a corner case for us, and we don't believe we're exceptional in this regard. The popular hiredis package for interfacing with redis from Node is also a binary module.
-
-
-[4] Note that I said this is an important principle for software version control, not using git in general. People use git for lots of things where checking in binaries and other derived files is probably fine. Also, I'm not interested in proselytizing; if you want to do this for software version control too, go ahead. But don't do it out of ignorance of existing successful software engineering practices.
diff --git a/doc/blog/npm/npm-1-0-global-vs-local-installation.md b/doc/blog/npm/npm-1-0-global-vs-local-installation.md
deleted file mode 100644
index 77a3fa895ea..00000000000
--- a/doc/blog/npm/npm-1-0-global-vs-local-installation.md
+++ /dev/null
@@ -1,64 +0,0 @@
-title: npm 1.0: Global vs Local installation
-author: Isaac Schlueter
-date: Wed Mar 23 2011 23:07:13 GMT-0700 (PDT)
-status: publish
-category: npm
-slug: npm-1-0-global-vs-local-installation
-
-npm 1.0 is in release candidate mode. Go get it!
-
-More than anything else, the driving force behind the npm 1.0 rearchitecture was the desire to simplify what a package installation directory structure looks like.
-
-In npm 0.x, there was a command called bundle that a lot of people liked. bundle let you install your dependencies locally in your project, but even still, it was basically a hack that never really worked very reliably.
-
-Also, there was that activation/deactivation thing. That’s confusing.
-
-Two paths
-
-In npm 1.0, there are two ways to install things:
-
- - globally —- This drops modules in
{prefix}/lib/node_modules, and puts executable files in {prefix}/bin, where {prefix} is usually something like /usr/local. It also installs man pages in {prefix}/share/man, if they’re supplied. - locally —- This installs your package in the current working directory. Node modules go in
./node_modules, executables go in ./node_modules/.bin/, and man pages aren’t installed at all.
-
-Which to choose
-
-Whether to install a package globally or locally depends on the global config, which is aliased to the -g command line switch.
-
-Just like how global variables are kind of gross, but also necessary in some cases, global packages are important, but best avoided if not needed.
-
-In general, the rule of thumb is:
-
- - If you’re installing something that you want to use in your program, using
require('whatever'), then install it locally, at the root of your project. - If you’re installing something that you want to use in your shell, on the command line or something, install it globally, so that its binaries end up in your
PATH environment variable.
-
-When you can't choose
-
-Of course, there are some cases where you want to do both. Coffee-script and Express both are good examples of apps that have a command line interface, as well as a library. In those cases, you can do one of the following:
-
- - Install it in both places. Seriously, are you that short on disk space? It’s fine, really. They’re tiny JavaScript programs.
- Install it globally, and then
npm link coffee-script or npm link express (if you’re on a platform that supports symbolic links.) Then you only need to update the global copy to update all the symlinks as well.
-
-The first option is the best in my opinion. Simple, clear, explicit. The second is really handy if you are going to re-use the same library in a bunch of different projects. (More on npm link in a future installment.)
-
-You can probably think of other ways to do it by messing with environment variables. But I don’t recommend those ways. Go with the grain.
-
-Slight exception: It’s not always the cwd.
-
-Let’s say you do something like this:
-
-cd ~/projects/foo # go into my project
-npm install express # ./node_modules/express
-cd lib/utils # move around in there
-vim some-thing.js # edit some stuff, work work work
-npm install redis # ./lib/utils/node_modules/redis!? ew.
-
-In this case, npm will install redis into ~/projects/foo/node_modules/redis. Sort of like how git will work anywhere within a git repository, npm will work anywhere within a package, defined by having a node_modules folder.
-
-Test runners and stuff
-
-If your package's scripts.test command uses a command-line program installed by one of your dependencies, not to worry. npm makes ./node_modules/.bin the first entry in the PATH environment variable when running any lifecycle scripts, so this will work fine, even if your program is not globally installed:
-
-
{ "name" : "my-program"
-, "version" : "1.2.3"
-, "dependencies": { "express": "*", "coffee-script": "*" }
-, "devDependencies": { "vows": "*" }
-, "scripts":
-  { "test": "vows test/*.js"
-  , "preinstall": "cake build" } }
diff --git a/doc/blog/npm/npm-1-0-link.md b/doc/blog/npm/npm-1-0-link.md
deleted file mode 100644
index 095ecb58b2f..00000000000
--- a/doc/blog/npm/npm-1-0-link.md
+++ /dev/null
@@ -1,114 +0,0 @@
-title: npm 1.0: link
-author: Isaac Schlueter
-date: Wed Apr 06 2011 17:40:33 GMT-0700 (PDT)
-status: publish
-category: npm
-slug: npm-1-0-link
-
-npm 1.0 is in release candidate mode. Go get it!
-
-In npm 0.x, there was a command called link. With it, you could “link-install” a package so that changes would be reflected in real-time. This is especially handy when you’re actually building something. You could make a few changes, run the command again, and voila, your new code would be run without having to re-install every time.
-
-Of course, compiled modules still have to be rebuilt. That’s not ideal, but it’s a problem that will take more powerful magic to solve.
-
-In npm 0.x, this was a pretty awful kludge. Back then, every package existed in some folder like:
-
-prefix/lib/node/.npm/my-package/1.3.6/package
-
-
-and the package’s version and name could be inferred from the path. Then, symbolic links were set up that looked like:
-
-prefix/lib/node/my-package@1.3.6 -> ./.npm/my-package/1.3.6/package
-
-
-It was easy enough to point that symlink to a different location. However, since the package.json file could change, that meant that the connection between the version and the folder was not reliable.
-
-At first, this was just sort of something that we dealt with by saying, “Relink if you change the version.” However, as more and more edge cases arose, eventually the solution was to give link packages this fakey version of “9999.0.0-LINK-hash” so that npm knew it was an impostor. Sometimes the package was treated as if it had the 9999.0.0 version, and other times it was treated as if it had the version specified in the package.json.
-
-A better way
-
-For npm 1.0, we backed up and looked at what the actual use cases were. Most of the time when you link something you want one of the following:
-
-
-- globally install this package I’m working on so that I can run the command it creates and test its stuff as I work on it.
-- locally install my thing into some other thing that depends on it, so that the other thing can
require() it.
-
-
-And, in both cases, changes should be immediately apparent and not require any re-linking.
-
-Also, there’s a third use case that I didn’t really appreciate until I started writing more programs that had more dependencies:
-
- Globally install something, and use it in development in a bunch of projects, and then update them all at once so that they all use the latest version.
-
-Really, the second case above is a special-case of this third case.
-
-Link devel → global
-
-The first step is to link your local project into the global install space. (See global vs local installation for more on this global/local business.)
-
-I do this as I’m developing node projects (including npm itself).
-
-cd ~/dev/js/node-tap # go into the project dir
-npm link # create symlinks into {prefix}
-
-
-Because of how I have my computer set up, with /usr/local as my install prefix, I end up with a symlink from /usr/local/lib/node_modules/tap pointing to ~/dev/js/node-tap, and the executable linked to /usr/local/bin/tap.
-
-Of course, if you set your paths differently, then you’ll have different results. (That’s why I tend to talk in terms of prefix rather than /usr/local.)
-
-Link global → local
-
-When you want to link the globally-installed package into your local development folder, you run npm link pkg where pkg is the name of the package that you want to install.
-
-For example, let’s say that I wanted to write some tap tests for my node-glob package. I’d first do the steps above to link tap into the global install space, and then I’d do this:
-
-cd ~/dev/js/node-glob # go to the project that uses the thing.
-npm link tap # link the global thing into my project.
-
-
-Now when I make changes in ~/dev/js/node-tap, they’ll be immediately reflected in ~/dev/js/node-glob/node_modules/tap.
-
-Link to stuff you don’t build
-
-Let’s say I have 15 sites that all use express. I want the benefits of local development, but I also want to be able to update all my dev folders at once. You can globally install express, and then link it into your local development folder.
-
-npm install express -g # install express globally
-cd ~/dev/js/my-blog # development folder one
-npm link express # link the global express into ./node_modules
-cd ~/dev/js/photo-site # other project folder
-npm link express # link express into here, as well
-
- # time passes
- # TJ releases some new stuff.
- # you want this new stuff.
-
-npm update express -g # update the global install.
- # this also updates my project folders.
-
-
-Caveat: Not For Real Servers
-
-npm link is a development tool. It’s awesome for managing packages on your local development box. But deploying with npm link is basically asking for problems, since it makes it super easy to update things without realizing it.
-
-Caveat 2: Sorry, Windows!
-
-I highly doubt that a native Windows node will ever have comparable symbolic link support to what Unix systems provide. I know that there are junctions and such, and I've heard legends about symbolic links on Windows 7.
-
-When there is a native windows port of Node, if that native windows port has `fs.symlink` and `fs.readlink` support that is exactly identical to the way that they work on Unix, then this should work fine.
-
-But I wouldn't hold my breath. Any bugs about this not working on a native Windows system (ie, not Cygwin) will most likely be closed with wontfix.
-
-
-Aside: Credit where Credit’s Due
-
-Back before the Great Package Management Wars of Node 0.1, before npm or kiwi or mode or seed.js could do much of anything, and certainly before any of them had more than 2 users, Mikeal Rogers invited me to the Couch.io offices for lunch to talk about this npm registry thingie I’d mentioned wanting to build. (That is, to convince me to use CouchDB for it.)
-
-Since he was volunteering to build the first version of it, and since couch is pretty much the ideal candidate for this use-case, it was an easy sell.
-
-While I was there, he said, “Look. You need to be able to link a project directory as if it was installed as a package, and then have it all Just Work. Can you do that?”
-
-I was like, “Well, I don’t know… I mean, there’s these edge cases, and it doesn’t really fit with the existing folder structure very well…”
-
-“Dude. Either you do it, or I’m going to have to do it, and then there’ll be another package manager in node, instead of writing a registry for npm, and it won’t be as good anyway. Don’t be python.”
-
-The rest is history.
diff --git a/doc/blog/npm/npm-1-0-released.md b/doc/blog/npm/npm-1-0-released.md
deleted file mode 100644
index d91b2793ea7..00000000000
--- a/doc/blog/npm/npm-1-0-released.md
+++ /dev/null
@@ -1,36 +0,0 @@
-title: npm 1.0: Released
-author: Isaac Schlueter
-date: Sun May 01 2011 08:09:45 GMT-0700 (PDT)
-status: publish
-category: npm
-slug: npm-1-0-released
-
-npm 1.0 has been released. Here are the highlights:
-
- - Global vs local installation
- ls displays a tree, instead of being a remote search
- No more “activation” concept - dependencies are nested
- Updates to link command
- Install script cleans up any 0.x cruft it finds. (That is, it removes old packages, so that they can be installed properly.)
- Simplified “search” command. One line per package, rather than one line per version.
- Renovated “completion” approach
- More help topics
- Simplified folder structure
-
-The focus is on npm being a development tool, rather than an apt-wannabe.
-
-Installing it
-
-To get the new version, run this command:
-
-curl http://npmjs.org/install.sh | sh
-
-This will prompt to ask you if it’s ok to remove all the old 0.x cruft. If you want to not be asked, then do this:
-
-curl http://npmjs.org/install.sh | clean=yes sh
-
-Or, if you want to not do the cleanup, and leave the old stuff behind, then do this:
-
-curl http://npmjs.org/install.sh | clean=no sh
-
-A lot of people in the node community were brave testers and helped make this release a lot better (and swifter) than it would have otherwise been. Thanks :)
-
-Code Freeze
-
-npm will not have any major feature enhancements or architectural changes for at least 6 months. There are interesting developments planned that leverage npm in some ways, but it’s time to let the client itself settle. Also, I want to focus attention on some other problems for a little while.
-
-Of course, bug reports are always welcome.
-
-See you at NodeConf!
diff --git a/doc/blog/npm/npm-1-0-the-new-ls.md b/doc/blog/npm/npm-1-0-the-new-ls.md
deleted file mode 100644
index 9fef76c315e..00000000000
--- a/doc/blog/npm/npm-1-0-the-new-ls.md
+++ /dev/null
@@ -1,144 +0,0 @@
-title: npm 1.0: The New "ls"
-author: Isaac Schlueter
-date: Thu Mar 17 2011 23:22:17 GMT-0700 (PDT)
-status: publish
-category: npm
-slug: npm-1-0-the-new-ls
-
-This is the first in a series of hopefully more than 1 posts, each detailing some aspect of npm 1.0.
-
-In npm 0.x, the ls command was a combination of both searching the registry as well as reporting on what you have installed.
-
-As the registry has grown in size, this has gotten unwieldy. Also, since npm 1.0 manages dependencies differently, nesting them in node_modules folder and installing locally by default, there are different things that you want to view.
-
-The functionality of the ls command was split into two different parts. search is now the way to find things on the registry (and it only reports one line per package, instead of one line per version), and ls shows a tree view of the packages that are installed locally.
-
-Here’s an example of the output:
-
-$ npm ls
-npm@1.0.0 /Users/isaacs/dev-src/js/npm
-├── semver@1.0.1
-├─┬ ronn@0.3.5
-│ └── opts@1.2.1
-└─┬ express@2.0.0rc3 extraneous
- ├─┬ connect@1.1.0
- │ ├── qs@0.0.7
- │ └── mime@1.2.1
- ├── mime@1.2.1
- └── qs@0.0.7
-
-
-This is after I’ve done npm install semver ronn express in the npm source directory. Since express isn’t actually a dependency of npm, it shows up with that “extraneous” marker.
-
-Let’s see what happens when we create a broken situation:
-
-$ rm -rf ./node_modules/express/node_modules/connect
-$ npm ls
-npm@1.0.0 /Users/isaacs/dev-src/js/npm
-├── semver@1.0.1
-├─┬ ronn@0.3.5
-│ └── opts@1.2.1
-└─┬ express@2.0.0rc3 extraneous
- ├── UNMET DEPENDENCY connect >= 1.1.0 < 2.0.0
- ├── mime@1.2.1
- └── qs@0.0.7
-
-
-Tree views are great for human readability, but some times you want to pipe that stuff to another program. For that output, I took the same datastructure, but instead of building up a treeview string for each line, it spits out just the folders like this:
-
-$ npm ls -p
-/Users/isaacs/dev-src/js/npm
-/Users/isaacs/dev-src/js/npm/node_modules/semver
-/Users/isaacs/dev-src/js/npm/node_modules/ronn
-/Users/isaacs/dev-src/js/npm/node_modules/ronn/node_modules/opts
-/Users/isaacs/dev-src/js/npm/node_modules/express
-/Users/isaacs/dev-src/js/npm/node_modules/express/node_modules/connect
-/Users/isaacs/dev-src/js/npm/node_modules/express/node_modules/connect/node_modules/qs
-/Users/isaacs/dev-src/js/npm/node_modules/express/node_modules/connect/node_modules/mime
-/Users/isaacs/dev-src/js/npm/node_modules/express/node_modules/mime
-/Users/isaacs/dev-src/js/npm/node_modules/express/node_modules/qs
-
-
-Since you sometimes want a bigger view, I added the --long option to (shorthand: -l) to spit out more info:
-
-$ npm ls -l
-npm@1.0.0
-│ /Users/isaacs/dev-src/js/npm
-│ A package manager for node
-│ git://github.com/isaacs/npm.git
-│ http://npmjs.org/
-├── semver@1.0.1
-│ ./node_modules/semver
-│ The semantic version parser used by npm.
-│ git://github.com/isaacs/node-semver.git
-├─┬ ronn@0.3.5
-│ │ ./node_modules/ronn
-│ │ markdown to roff and html converter
-│ └── opts@1.2.1
-│ ./node_modules/ronn/node_modules/opts
-│ Command line argument parser written in the style of commonjs. To be used with node.js
-└─┬ express@2.0.0rc3 extraneous
- │ ./node_modules/express
- │ Sinatra inspired web development framework
- ├─┬ connect@1.1.0
- │ │ ./node_modules/express/node_modules/connect
- │ │ High performance middleware framework
- │ │ git://github.com/senchalabs/connect.git
- │ ├── qs@0.0.7
- │ │ ./node_modules/express/node_modules/connect/node_modules/qs
- │ │ querystring parser
- │ └── mime@1.2.1
- │ ./node_modules/express/node_modules/connect/node_modules/mime
- │ A comprehensive library for mime-type mapping
- ├── mime@1.2.1
- │ ./node_modules/express/node_modules/mime
- │ A comprehensive library for mime-type mapping
- └── qs@0.0.7
- ./node_modules/express/node_modules/qs
- querystring parser
-
-$ npm ls -lp
-/Users/isaacs/dev-src/js/npm:npm@1.0.0::::
-/Users/isaacs/dev-src/js/npm/node_modules/semver:semver@1.0.1::::
-/Users/isaacs/dev-src/js/npm/node_modules/ronn:ronn@0.3.5::::
-/Users/isaacs/dev-src/js/npm/node_modules/ronn/node_modules/opts:opts@1.2.1::::
-/Users/isaacs/dev-src/js/npm/node_modules/express:express@2.0.0rc3:EXTRANEOUS:::
-/Users/isaacs/dev-src/js/npm/node_modules/express/node_modules/connect:connect@1.1.0::::
-/Users/isaacs/dev-src/js/npm/node_modules/express/node_modules/connect/node_modules/qs:qs@0.0.7::::
-/Users/isaacs/dev-src/js/npm/node_modules/express/node_modules/connect/node_modules/mime:mime@1.2.1::::
-/Users/isaacs/dev-src/js/npm/node_modules/express/node_modules/mime:mime@1.2.1::::
-/Users/isaacs/dev-src/js/npm/node_modules/express/node_modules/qs:qs@0.0.7::::
-
-
-And, if you want to get at the globally-installed modules, you can use ls with the global flag:
-
-$ npm ls -g
-/usr/local
-├─┬ A@1.2.3 -> /Users/isaacs/dev-src/js/A
-│ ├── B@1.2.3 -> /Users/isaacs/dev-src/js/B
-│ └─┬ npm@0.3.15
-│ └── semver@1.0.1
-├─┬ B@1.2.3 -> /Users/isaacs/dev-src/js/B
-│ └── A@1.2.3 -> /Users/isaacs/dev-src/js/A
-├── glob@2.0.5
-├─┬ npm@1.0.0 -> /Users/isaacs/dev-src/js/npm
-│ ├── semver@1.0.1
-│ └─┬ ronn@0.3.5
-│ └── opts@1.2.1
-└── supervisor@0.1.2 -> /Users/isaacs/dev-src/js/node-supervisor
-
-$ npm ls -gpl
-/usr/local:::::
-/usr/local/lib/node_modules/A:A@1.2.3::::/Users/isaacs/dev-src/js/A
-/usr/local/lib/node_modules/A/node_modules/npm:npm@0.3.15::::/Users/isaacs/dev-src/js/A/node_modules/npm
-/usr/local/lib/node_modules/A/node_modules/npm/node_modules/semver:semver@1.0.1::::/Users/isaacs/dev-src/js/A/node_modules/npm/node_modules/semver
-/usr/local/lib/node_modules/B:B@1.2.3::::/Users/isaacs/dev-src/js/B
-/usr/local/lib/node_modules/glob:glob@2.0.5::::
-/usr/local/lib/node_modules/npm:npm@1.0.0::::/Users/isaacs/dev-src/js/npm
-/usr/local/lib/node_modules/npm/node_modules/semver:semver@1.0.1::::/Users/isaacs/dev-src/js/npm/node_modules/semver
-/usr/local/lib/node_modules/npm/node_modules/ronn:ronn@0.3.5::::/Users/isaacs/dev-src/js/npm/node_modules/ronn
-/usr/local/lib/node_modules/npm/node_modules/ronn/node_modules/opts:opts@1.2.1::::/Users/isaacs/dev-src/js/npm/node_modules/ronn/node_modules/opts
-/usr/local/lib/node_modules/supervisor:supervisor@0.1.2::::/Users/isaacs/dev-src/js/node-supervisor
-
-
-Those -> flags are indications that the package is link-installed, which will be covered in the next installment.
diff --git a/doc/blog/npm/peer-dependencies.md b/doc/blog/npm/peer-dependencies.md
deleted file mode 100644
index 2baab8799a8..00000000000
--- a/doc/blog/npm/peer-dependencies.md
+++ /dev/null
@@ -1,134 +0,0 @@
-category: npm
-title: Peer Dependencies
-date: 2013-02-08T00:00:00Z
-author: Domenic Denicola
-slug: peer-dependencies
-
-Reposted from [Domenic's
-blog](http://domenic.me/2013/02/08/peer-dependencies/) with
-permission. Thanks!
-
-npm is awesome as a package manager. In particular, it handles sub-dependencies very well: if my package depends on
-`request` version 2 and `some-other-library`, but `some-other-library` depends on `request` version 1, the resulting
-dependency graph looks like:
-
-```text
-├── request@2.12.0
-└─┬ some-other-library@1.2.3
- └── request@1.9.9
-```
-
-This is, generally, great: now `some-other-library` has its own copy of `request` v1 that it can use, while not
-interfering with my package's v2 copy. Everyone's code works!
-
-## The Problem: Plugins
-
-There's one use case where this falls down, however: *plugins*. A plugin package is meant to be used with another "host"
-package, even though it does not always directly *use* the host package. There are many examples of this pattern in the
-Node.js package ecosystem already:
-
-- Grunt [plugins](http://gruntjs.com/#plugins-all)
-- Chai [plugins](http://chaijs.com/plugins)
-- LevelUP [plugins](https://github.com/rvagg/node-levelup/wiki/Modules)
-- Express [middleware](http://expressjs.com/api.html#middleware)
-- Winston [transports](https://github.com/flatiron/winston/blob/master/docs/transports.md)
-
-Even if you're not familiar with any of those use cases, surely you recall "jQuery plugins" from back when you were a
-client-side developer: little `
-  -
 -
-Inspired by process visualization, we discovered pattern, form, and by relief, the hex shape. The angled infrastructure encourages energy to move through the letterforms.
-
-
 -
-This language can expand into the organic network topography of Node or distill down into a single hex connection point.
-
-This scaling represents the dynamic nature of Node in a simple, distinct manner.
-
-
 -
-We look forward to exploring this visual language as the technology charges into a very promising future.
-
-
 -
-We hope you'll have fun using it.
-
-To download the new logo, visit
 diff --git a/doc/blog/Uncategorized/growing-up.md b/doc/blog/Uncategorized/growing-up.md
deleted file mode 100644
index 10e1d58d006..00000000000
--- a/doc/blog/Uncategorized/growing-up.md
+++ /dev/null
@@ -1,12 +0,0 @@
-title: Growing up
-author: ryandahl
-date: Thu Dec 15 2011 11:59:15 GMT-0800 (PST)
-status: publish
-category: Uncategorized
-slug: growing-up
-
-This week Microsoft announced